AI chatbots now solve everything from a restaurant tip to a college calculus exam, and dedicated math apps can read a photo of handwritten homework. The answers are not always right, and a wrong answer can look just as confident as a correct one. To find out which AI is best for mathematics, our research team ran a head-to-head study from September 29 to October 16, 2026.
We gave the same 540 math problems to ten AI platforms: seven general AI chatbots and three math apps, Wolfram Alpha, Photomath and Symbolab. The problems covered nine tasks, with 60 problems each, from middle school arithmetic to competition problems, and produced 5,040 solutions. The math apps were not tested on proofs or competition problems, which they are not built to handle. A panel of five mathematicians and math teachers scored each solution from 0 to 100 for a correct answer and sound reasoning, without knowing which platform wrote it. We also checked every final answer against a known solution and read every step of every correct answer.
Summary of Findings
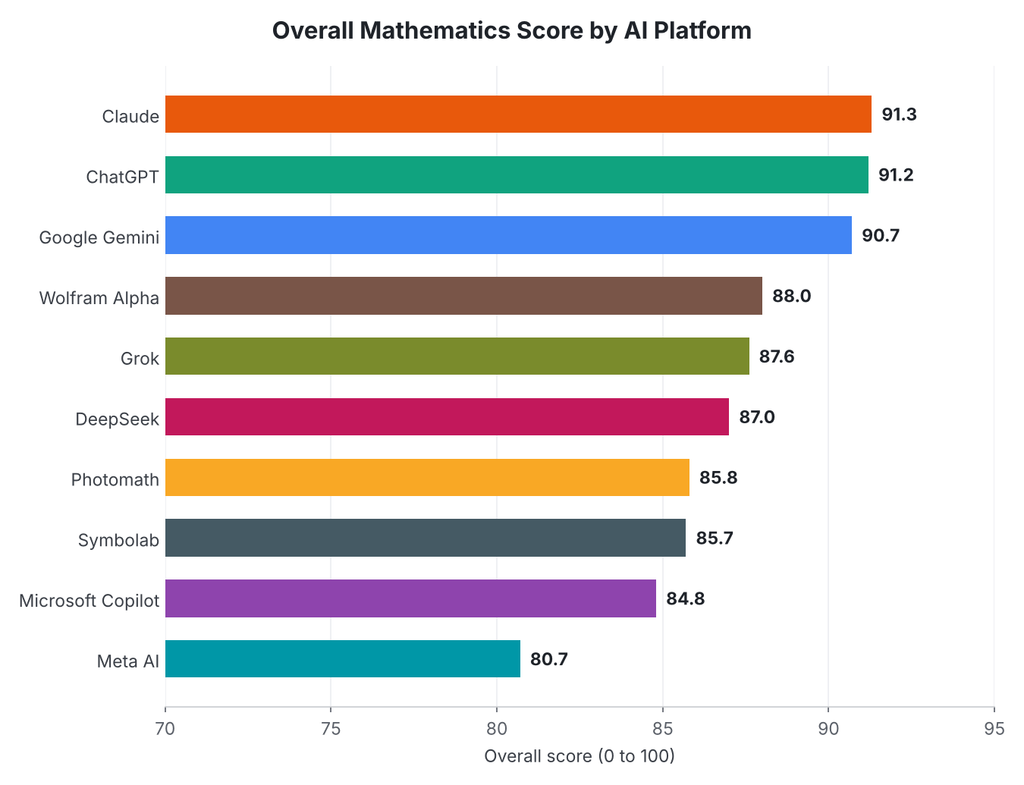
- Claude is the best AI for mathematics overall, scoring 91.3 out of 100 with Claude Opus 5.5, just ahead of ChatGPT at 91.2 and Google Gemini at 90.7.
- Claude won three of the nine tasks: algebra (92.8), word problems (92.6) and proofs (93.8). Wolfram Alpha led everyday math and calculus, and Photomath led solving from a photo of handwritten work.
- ChatGPT solved the most competition problems correctly (81.7%), and every platform made more mistakes as problems got harder.
- Among the chatbots, Claude showed the fewest flawed steps in its correct answers (2.1%), compared with 8.7% for Meta AI.
Best AI for Mathematics Overall
Each platform was tested on its best available model or plan. A platform’s overall score is the average of its scores across the tasks in our study, with each task weighted equally. The three math apps were scored on seven tasks, without proofs and competition problems. In the table below, we rank the ten platforms from highest to lowest.
Mathematics Scores by AI Platform (September to October 2026)
| Rank | AI Platform | Model or Plan Tested | Overall Score | Strongest Task |
| 1 | Claude | Claude Opus 5.5 | 91.3 | Proofs |
| 2 | ChatGPT | GPT-6 Sol | 91.2 | Everyday Math |
| 3 | Google Gemini | Gemini 4 Argon | 90.7 | Everyday Math |
| 4 | Wolfram Alpha | Wolfram Alpha Pro | 88.0 | Everyday Math |
| 5 | Grok | Grok 4.6 | 87.6 | Everyday Math |
| 6 | DeepSeek | DeepSeek V4-Pro | 87.0 | Everyday Math |
| 7 | Photomath | Photomath Plus | 85.8 | Photo of Handwritten Work |
| 8 | Symbolab | Symbolab Pro | 85.7 | Everyday Math |
| 9 | Microsoft Copilot | GPT-6 Astra | 84.8 | Everyday Math |
| 10 | Meta AI | Muse Spark | 80.7 | Everyday Math |
Our researchers took three main points from this data:
- We found that Claude and ChatGPT are almost tied, separated by 0.1 points. ChatGPT finished first or second in seven of the nine tasks and Claude in five, and Claude’s lead came from proofs and word problems, where it explained each step most clearly.
- Wolfram Alpha was the highest-ranked math app, in fourth place at 88.0. It computes answers with a math engine, so it led everyday math (94.6) and calculus (93.1), but it struggled with word problems (82.7) written in everyday language.
- Meta AI ranked last at 80.7. Its lowest score was on competition problems (74.6).
Best AI for Each Type of Math
We split the problems evenly across nine tasks, with 60 problems per task. The first table below shows the winner and runner-up for each task. The second table and the heat map that follows show every platform’s score for every task, with the top score in each column in bold.
Best AI Platform for Each Math Task (September to October 2026)
| Math Task | Best Platform | Score | Runner-Up | Score |
| Everyday Math | Wolfram Alpha | 94.6 | Claude | 93.4 |
| Algebra | Claude | 92.8 | ChatGPT | 92.2 |
| Geometry | Google Gemini | 91.2 | ChatGPT | 90.4 |
| Calculus | Wolfram Alpha | 93.1 | ChatGPT | 92.3 |
| Statistics and Probability | ChatGPT | 91.6 | Claude | 90.9 |
| Word Problems | Claude | 92.6 | ChatGPT | 91.4 |
| Proofs | Claude | 93.8 | ChatGPT | 91.2 |
| Photo of Handwritten Work | Photomath | 91.6 | Google Gemini | 90.8 |
| Competition Problems | ChatGPT | 90.1 | Google Gemini | 89.7 |
Mathematics Scores by Task and AI Platform (September to October 2026)
| AI Platform | Everyday | Algebra | Geometry | Calculus | Statistics | Word Problems | Proofs | Photo | Competition |
| Claude | 93.4 | 92.8 | 89.6 | 91.7 | 90.9 | 92.6 | 93.8 | 87.2 | 89.3 |
| ChatGPT | 93.1 | 92.2 | 90.4 | 92.3 | 91.6 | 91.4 | 91.2 | 88.6 | 90.1 |
| Google Gemini | 92.4 | 91.3 | 91.2 | 90.6 | 89.8 | 90.2 | 90.4 | 90.8 | 89.7 |
| Wolfram Alpha | 94.6 | 91.6 | 85.2 | 93.1 | 90.4 | 82.7 | N/A | 78.4 | N/A |
| Grok | 90.6 | 89.4 | 85.7 | 89.2 | 87.6 | 87.9 | 86.3 | 84.1 | 87.8 |
| DeepSeek | 90.2 | 89.8 | 84.9 | 89.6 | 87.1 | 86.4 | 87.2 | 80.6 | 86.9 |
| Photomath | 91.2 | 88.4 | 83.6 | 85.1 | 79.8 | 80.6 | N/A | 91.6 | N/A |
| Symbolab | 90.8 | 89.7 | 84.1 | 88.9 | 80.6 | 79.4 | N/A | 86.3 | N/A |
| Microsoft Copilot | 89.7 | 86.9 | 83.4 | 85.8 | 85.2 | 85.6 | 82.1 | 83.9 | 80.4 |
| Meta AI | 86.4 | 82.7 | 79.8 | 80.3 | 81.4 | 82.9 | 76.8 | 81.2 | 74.6 |
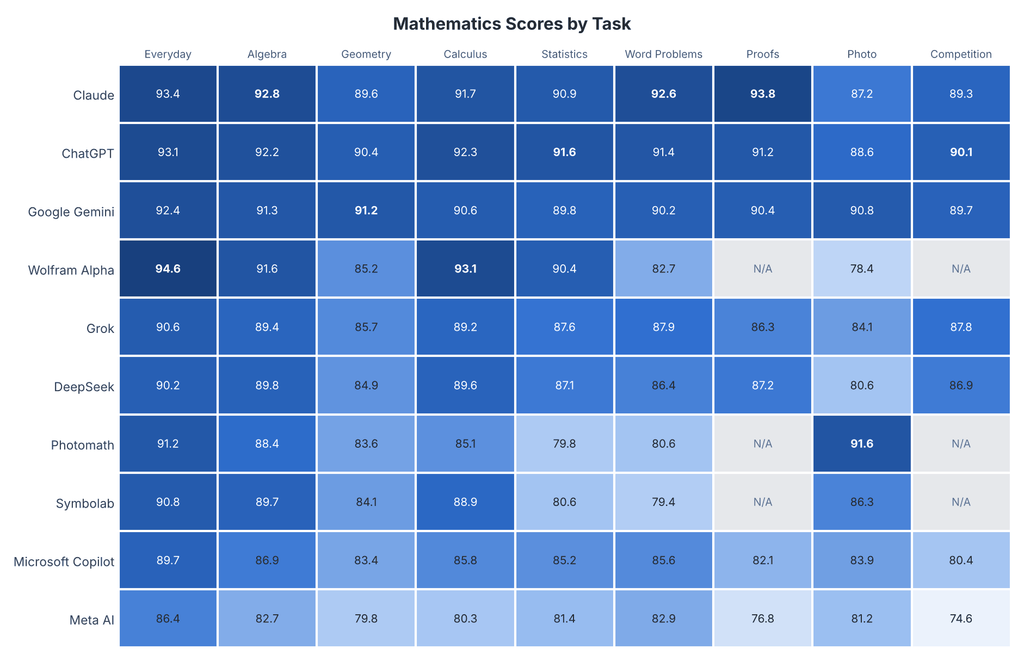
Here is what our team took from the task-level results:
- We found that five different platforms won at least one task. Claude won three, ChatGPT and Wolfram Alpha won two each, and Google Gemini and Photomath won one each.
- Proofs produced the widest gap of any task, 17.0 points between Claude (93.8) and Meta AI (76.8). Photomath led solving from a photo of handwritten work (91.6) because it is built to read handwriting, and Google Gemini was the strongest chatbot on that task (90.8).
- ChatGPT led competition problems (90.1) and statistics and probability (91.6). Google Gemini led geometry (91.2), helped by drawing and labeling diagrams as it worked.
Accuracy: Right Answers, Sound Steps and Reading Handwriting
A math answer is only useful if it is right. We checked every final answer against a known solution and grouped the problems into four difficulty levels, from middle school to competition problems. For every correct answer, the panel also read each step and counted answers that reached the right result through a wrong step, which can teach the wrong method. Finally, we counted how often each platform misread a number or symbol in the 60 photos of handwritten work.
Math Accuracy by AI Platform (September to October 2026)
| AI Platform | Middle School Answers Correct | High School Answers Correct | College Answers Correct | Competition Answers Correct | Correct Answers With a Flawed Step | Photos Misread |
| Claude | 99.2% | 97.6% | 94.1% | 78.3% | 2.1% | 5.4% |
| ChatGPT | 99.4% | 97.9% | 94.6% | 81.7% | 3.4% | 4.2% |
| Google Gemini | 99.1% | 97.2% | 93.4% | 79.6% | 3.9% | 3.1% |
| Wolfram Alpha | 99.6% | 96.8% | 93.9% | N/A | 0.4% | 13.6% |
| Grok | 98.6% | 95.4% | 90.2% | 72.4% | 6.2% | 7.8% |
| DeepSeek | 98.9% | 96.1% | 91.8% | 74.6% | 5.1% | 11.2% |
| Photomath | 98.8% | 94.2% | 84.7% | N/A | 1.9% | 2.3% |
| Symbolab | 98.7% | 95.1% | 89.6% | N/A | 1.2% | 5.9% |
| Microsoft Copilot | 98.1% | 93.7% | 86.4% | 61.2% | 5.8% | 6.6% |
| Meta AI | 96.4% | 89.8% | 79.2% | 48.6% | 8.7% | 9.4% |
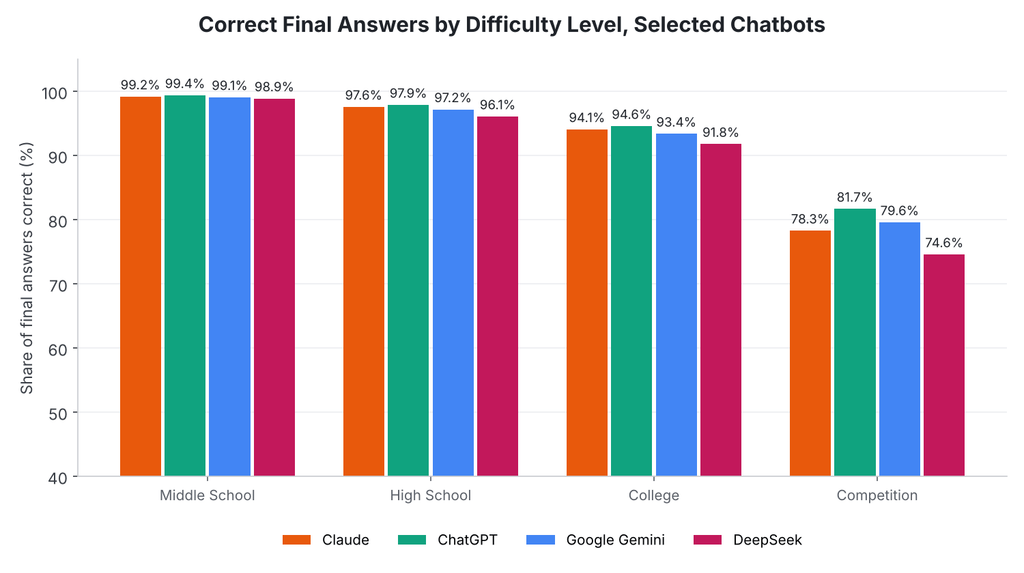
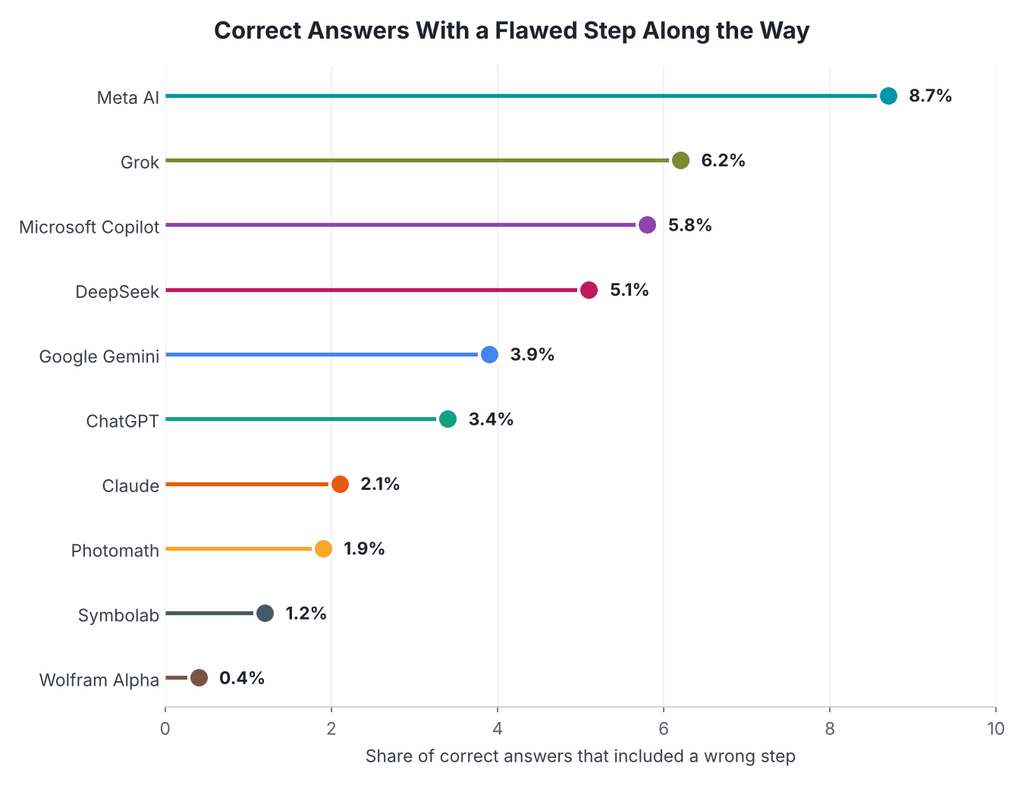
Our researchers drew three conclusions from the accuracy data:
- We found that every platform was close to perfect on middle school problems, with at least 96.4% correct, but accuracy fell as problems got harder. On competition problems, ChatGPT was right 81.7% of the time and Meta AI 48.6%.
- Wolfram Alpha almost never reached a right answer through a wrong step (0.4%), because a math engine computes every step. Among the chatbots, Claude had the lowest rate at 2.1%, while Meta AI reached 8.7%.
- Photomath misread the fewest photos of handwritten work (2.3%), followed by Google Gemini (3.1%). DeepSeek misread 11.2%, and Wolfram Alpha misread 13.6%, the most in the study.
Competition Math and the Hardest Problems
Competition problems are the hardest test of mathematical reasoning. Our 60 competition problems were new problems written in the style of national olympiads, so no platform could have seen them before. The table below shows each chatbot’s share of correct answers on them and how far its accuracy fell from middle school problems.
Competition Problem Accuracy by AI Chatbot (September to October 2026)
| AI Chatbot | Competition Answers Correct | Middle School Answers Correct | Drop (Points) |
| ChatGPT | 81.7% | 99.4% | 17.7 |
| Google Gemini | 79.6% | 99.1% | 19.5 |
| Claude | 78.3% | 99.2% | 20.9 |
| DeepSeek | 74.6% | 98.9% | 24.3 |
| Grok | 72.4% | 98.6% | 26.2 |
| Microsoft Copilot | 61.2% | 98.1% | 36.9 |
| Meta AI | 48.6% | 96.4% | 47.8 |
Here is what our team took from the competition results:
- We found that ChatGPT (81.7%), Google Gemini (79.6%) and Claude (78.3%) solved about four of every five competition problems.
- Meta AI’s accuracy fell the most, 47.8 points from middle school problems to competition problems, and Microsoft Copilot fell 36.9 points.
- These results match the progress of the strongest AI systems on real competitions. In July 2025, an advanced version of Gemini with Deep Think became the first AI system officially graded at gold-medal level at the International Mathematical Olympiad.
Best AI Models for Mathematics, Including Free Options
Most platforms give free users a different model or fewer features than paying subscribers. We tested 16 models and plans across the ten platforms, including each platform’s free option. The table below ranks every one we tested.
Mathematics Scores by Model and Plan (September to October 2026)
| Rank | Model or Plan | Platform | Available On | Score |
| 1 | Claude Opus 5.5 | Claude | Paid | 91.3 |
| 2 | GPT-6 Sol | ChatGPT | Paid | 91.2 |
| 3 | Gemini 4 Argon | Google Gemini | Paid | 90.7 |
| 4 | Claude Sonnet 5.5 | Claude | Free and paid | 90.4 |
| 5 | Gemini 3.8 Flash | Google Gemini | Free and paid | 89.3 |
| 6 | GPT-6 Luna | ChatGPT | Free and paid | 88.7 |
| 7 | Wolfram Alpha Pro | Wolfram Alpha | Paid | 88.0 |
| 8 | Grok 4.6 | Grok | Free and paid | 87.6 |
| 9 | DeepSeek V4-Pro | DeepSeek | Free | 87.0 |
| 10 | Wolfram Alpha (free) | Wolfram Alpha | Free | 86.1 |
| 11 | Photomath Plus | Photomath | Paid | 85.8 |
| 12 | Symbolab Pro | Symbolab | Paid | 85.7 |
| 13 | GPT-6 Astra | Microsoft Copilot | Free and paid | 84.8 |
| 14 | Photomath (free) | Photomath | Free | 84.1 |
| 15 | Symbolab (free) | Symbolab | Free | 84.0 |
| 16 | Muse Spark | Meta AI | Free | 80.7 |
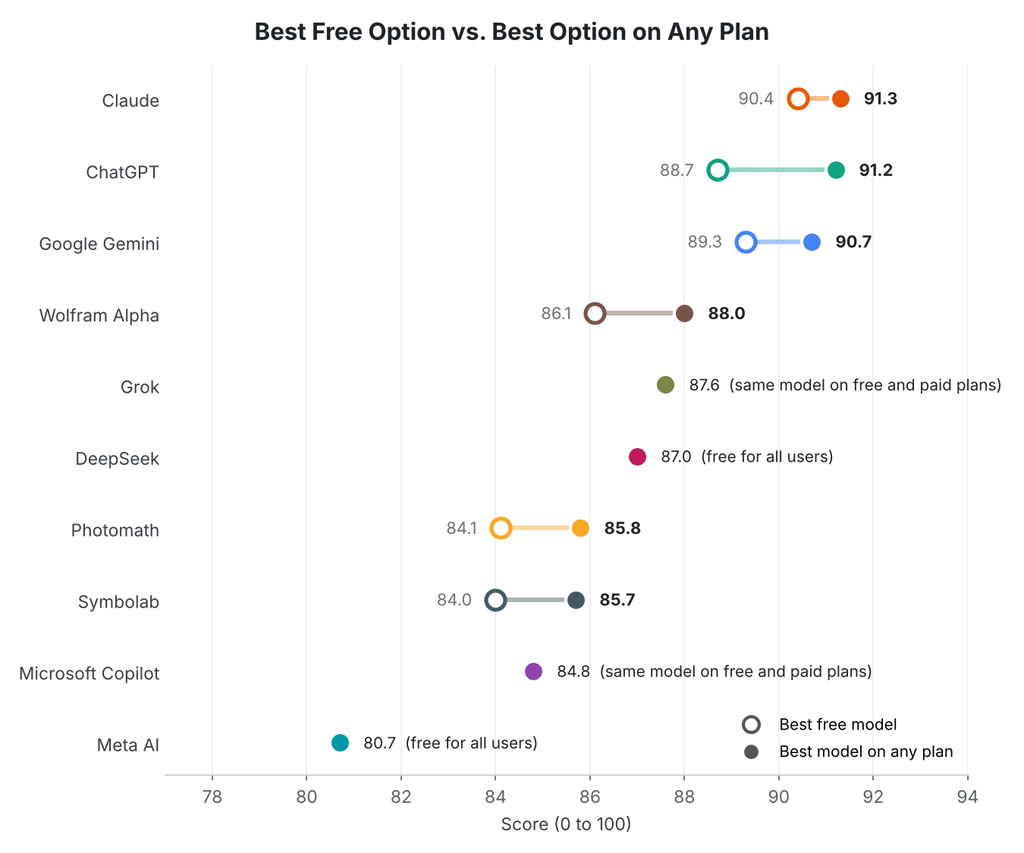
Our team took three main points from the model-level results:
- We found that Claude Sonnet 5.5 is the best free AI for mathematics, scoring 90.4, behind only three paid models.
- Paying for ChatGPT added the most of any platform: GPT-6 Sol scored 2.5 points higher than the free GPT-6 Luna, mostly on competition problems.
- Wolfram Alpha’s free version scored 86.1, 1.9 points below Wolfram Alpha Pro, which adds step-by-step solutions and photo input.
Requesting a Copy of This Report
If you’d like to request a PDF copy of this report or learn more about our agency, you can reach out here.
- First Page Sage Research Study, First Page Sage, September to October 2026, San Francisco, California
- Advanced Version of Gemini With Deep Think Officially Achieves Gold-Medal Standard at the International Mathematical Olympiad, Google DeepMind, July 2025, London, United Kingdom
- Google DeepMind Makes AI History With Gold Medal Win at World’s Toughest Math Competition, VentureBeat, July 2025, San Francisco, California
- Introducing Claude Sonnet 5.5, Anthropic, September 2026, San Francisco, California
- GPT-6 and Intelligent UI for Everyone, OpenAI, October 2026, San Francisco, California