AI now writes a large share of the world’s code, from quick scripts to full applications built by people who have never programmed. To find out which AI is best for coding, our research team ran a head-to-head study from September 30 to October 16, 2026.
The study had three parts. First, we gave the same 400 coding tasks to seven AI chat platforms, producing 2,800 solutions across eight types of coding work, and ran every solution against hidden unit tests. A panel of five senior software engineers also scored each solution from 0 to 100 for correctness, readability and security. Second, we gave seven AI coding agents the same 120 tasks from real open-source repositories. Third, we asked people with no coding experience to build the same 60 app ideas with four vibe coding tools.
Summary of Findings
- Claude is the best AI for coding overall, scoring 92.1 out of 100 with Claude Opus 5.5, followed by ChatGPT at 90.9 and Google Gemini at 89.0.
- Claude won six of the eight coding tasks. ChatGPT won explaining code and Gemini won data and SQL.
- Claude Code was the best coding agent, completing 78.3% of real repository tasks, ahead of OpenAI Codex at 74.6% and Cursor at 71.9%.
- Lovable was the best tool for vibe coding: 62.1% of apps worked on the first try and 88.3% worked after three fix requests.
Best AI for Coding Overall
This section covers the AI chat platforms most people use for coding help. Each platform was tested on its best available model. A platform’s overall score is the average of its scores across the eight coding tasks, with each task weighted equally. In the table below, we rank the seven platforms from highest to lowest.
Coding Scores by AI Platform (September to October 2026)
| Rank | AI Platform | Model Tested | Overall Score | Strongest Task |
| 1 | Claude | Claude Opus 5.5 | 92.1 | Refactoring |
| 2 | ChatGPT | GPT-6 Sol | 90.9 | Explaining Code |
| 3 | Google Gemini | Gemini 4 Argon | 89.0 | Data and SQL |
| 4 | Grok | Grok 4.6 | 85.1 | Writing New Code |
| 5 | DeepSeek | DeepSeek V4-Pro | 84.2 | Data and SQL |
| 6 | Microsoft Copilot | GPT-6 Astra | 83.0 | Explaining Code |
| 7 | Meta AI | Muse Spark | 77.5 | Explaining Code |
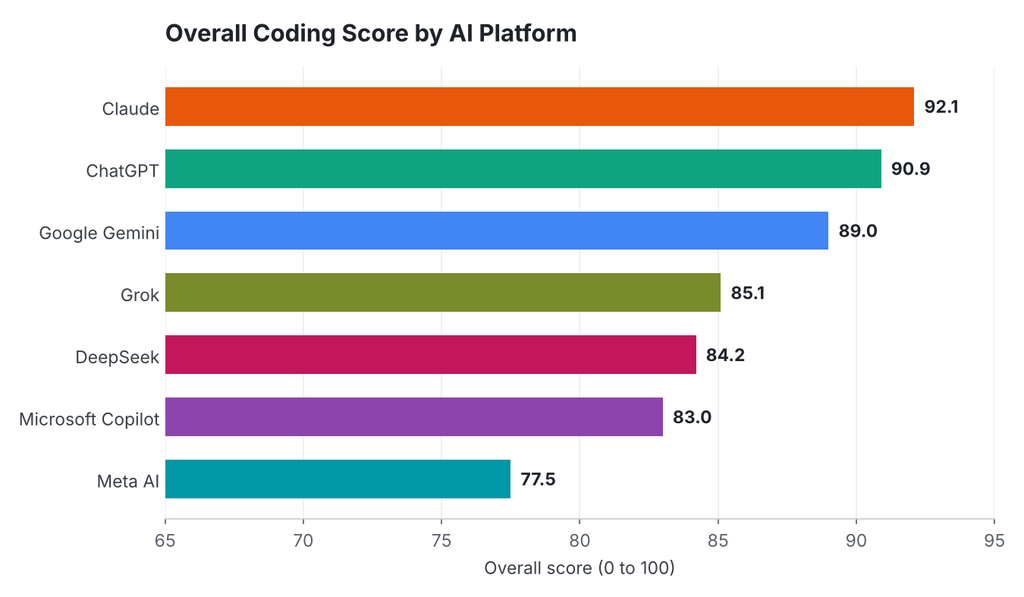
Our researchers took three main points from this data:
- We found that Claude led ChatGPT by 1.2 points and finished first in six of the eight tasks. Engineers on the panel rated its code the easiest to read and maintain.
- DeepSeek, which is free for everyone, scored 84.2, within 0.9 points of Grok. Its best task was data and SQL (86.2).
- Microsoft Copilot ranked sixth overall but scored 86.3 for explaining code, its strongest task. Developers who want a coding assistant from Microsoft are better served by GitHub Copilot, covered below.
Best AI for Each Coding Task
The tasks were split evenly across eight types of coding work, with 50 tasks each, in Python, JavaScript, TypeScript, Java, Go and SQL. The first table below shows the winner and runner-up for each task. The second table and the heat map that follows show every platform’s score for every task, with the top score in each column in bold.
Best AI Platform for Each Coding Task (September to October 2026)
| Coding Task | Best Platform | Score | Runner-Up | Score |
| Writing New Code | Claude | 93.1 | ChatGPT | 91.4 |
| Debugging | Claude | 92.4 | ChatGPT | 90.8 |
| Code Review | Claude | 91.8 | ChatGPT | 90.2 |
| Refactoring | Claude | 93.6 | ChatGPT | 89.7 |
| Writing Tests | Claude | 91.2 | ChatGPT | 90.6 |
| Explaining Code | ChatGPT | 93.2 | Claude | 92.7 |
| Data and SQL | Google Gemini | 91.8 | ChatGPT | 91.2 |
| Web Front-End | Claude | 92.9 | ChatGPT | 89.8 |
Coding Scores by Task and AI Platform (September to October 2026)
| AI Platform | New Code | Debugging | Code Review | Refactoring | Tests | Explaining | Data and SQL | Front-End |
| Claude | 93.1 | 92.4 | 91.8 | 93.6 | 91.2 | 92.7 | 89.4 | 92.9 |
| ChatGPT | 91.4 | 90.8 | 90.2 | 89.7 | 90.6 | 93.2 | 91.2 | 89.8 |
| Google Gemini | 89.2 | 88.6 | 87.9 | 87.4 | 88.1 | 90.1 | 91.8 | 88.7 |
| Grok | 86.7 | 85.9 | 83.6 | 84.8 | 84.1 | 85.2 | 84.3 | 86.1 |
| DeepSeek | 85.9 | 84.2 | 82.7 | 83.9 | 83.5 | 84.6 | 86.2 | 82.4 |
| Microsoft Copilot | 83.6 | 82.9 | 81.4 | 82.2 | 81.7 | 86.3 | 83.8 | 81.9 |
| Meta AI | 78.4 | 77.1 | 76.3 | 76.8 | 75.9 | 80.2 | 77.6 | 78.1 |
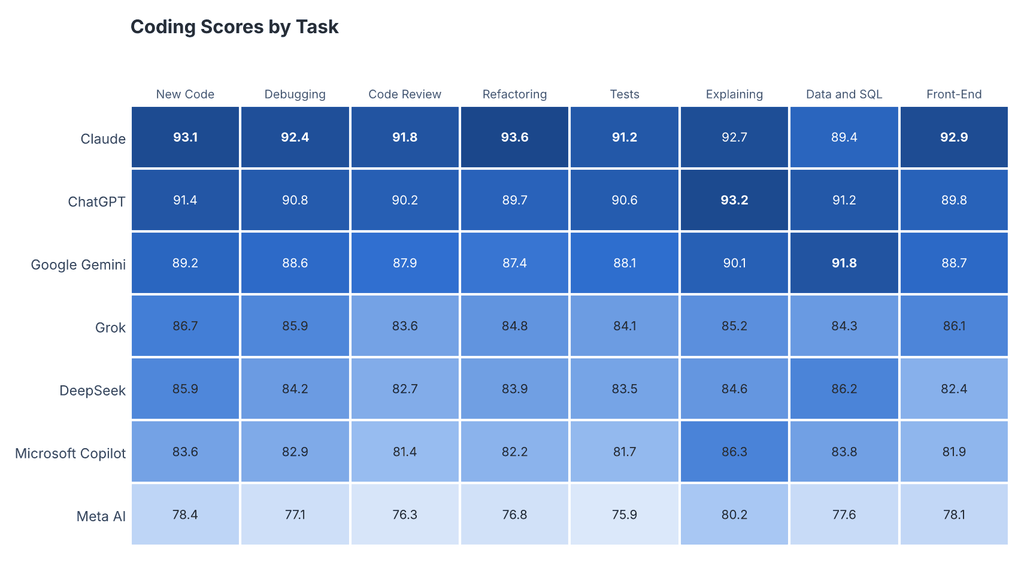
Here is what our team took from the task-level results:
- We found that Claude’s biggest margin came in refactoring (93.6), where it kept existing behavior intact while simplifying the code. ChatGPT finished 3.9 points behind.
- ChatGPT won explaining code (93.2), making it a strong choice for students and anyone learning to program.
- Google Gemini won data and SQL (91.8). Its queries were the most likely to run correctly against our test databases on the first attempt.
Code That Works on the First Try
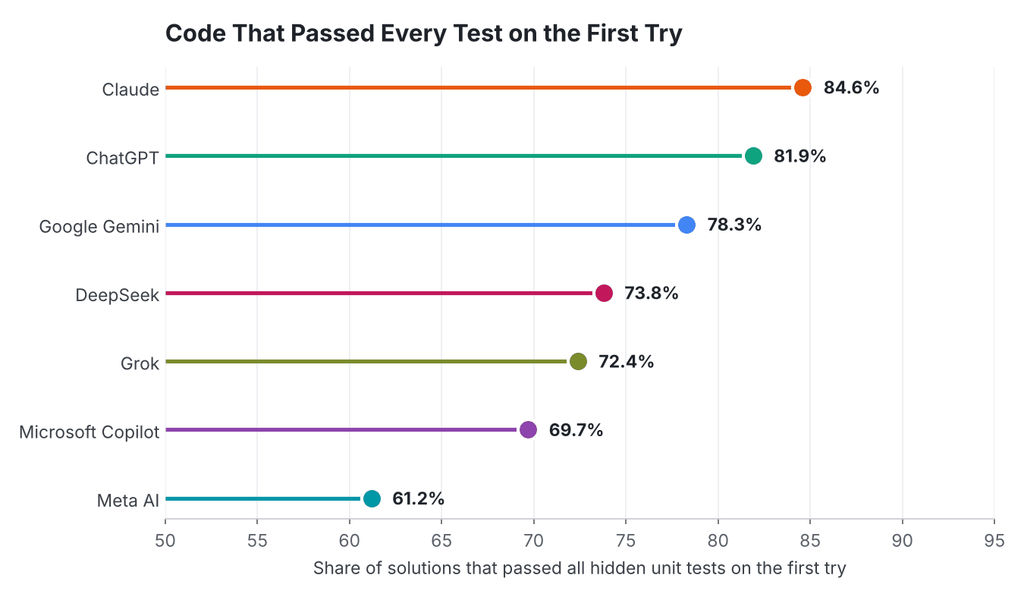
A score from expert judges tells part of the story. The other part is whether the code runs. Every solution in the study was run against a set of hidden unit tests that the platforms never saw, and we counted a solution as passing only if it passed every test without any changes.
First-Try Unit Test Pass Rate by AI Platform (September to October 2026)
| AI Platform | Solutions That Passed Every Test on the First Try |
| Claude | 84.6% |
| ChatGPT | 81.9% |
| Google Gemini | 78.3% |
| DeepSeek | 73.8% |
| Grok | 72.4% |
| Microsoft Copilot | 69.7% |
| Meta AI | 61.2% |
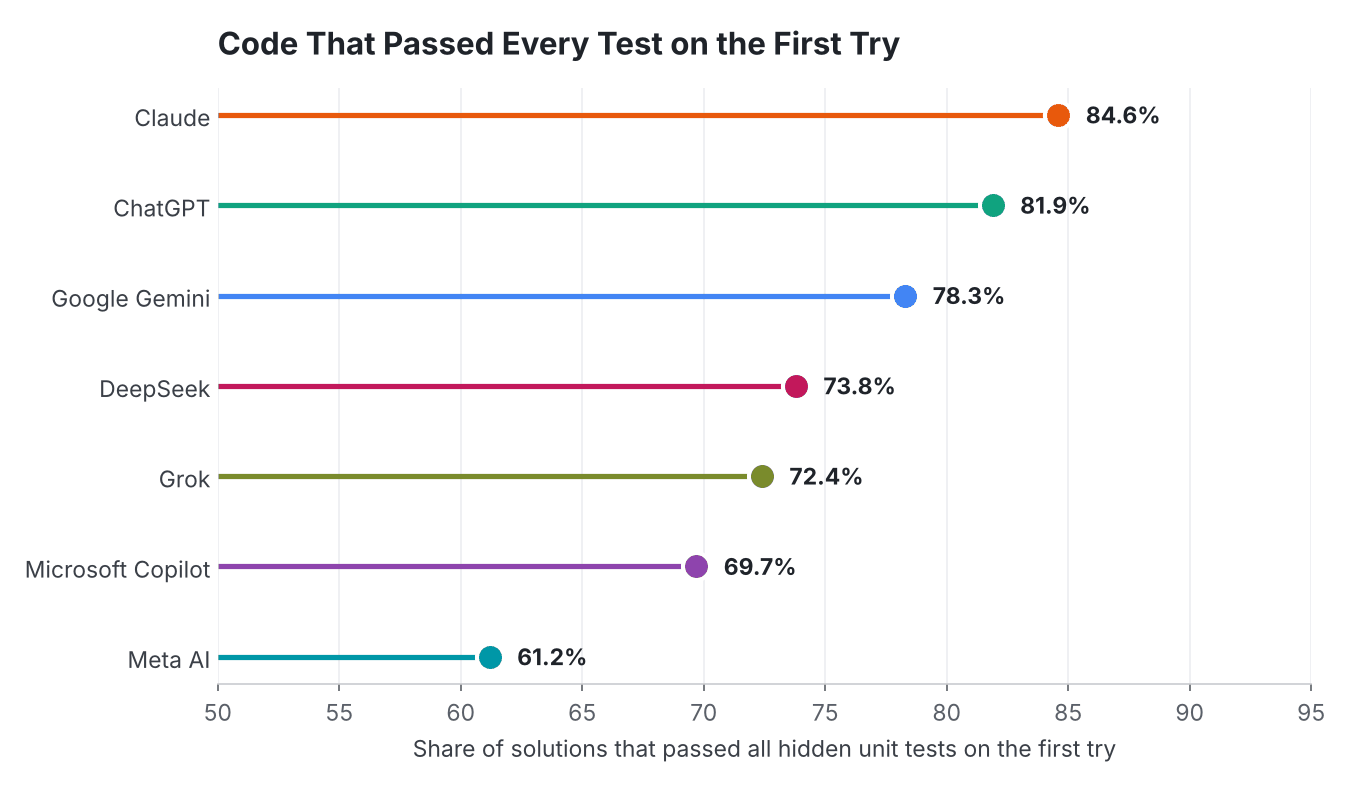
Our researchers drew three conclusions from the test results:
- We found that 84.6% of Claude’s solutions passed every test on the first try, 2.7 points ahead of ChatGPT.
- DeepSeek’s pass rate (73.8%) was higher than Grok’s (72.4%), even though Grok scored higher with the engineering panel, because DeepSeek’s code was plainer and less likely to break edge cases.
- Meta AI passed 61.2% of the time, so roughly two in five of its solutions needed fixing before they worked.
Best AI Coding Agents and Tools
Professional developers increasingly use coding agents that read a whole codebase, make changes across many files and run the tests themselves. We gave each agent the same 120 tasks taken from real open-source repositories, such as fixing a reported bug or adding a small feature. A task counted as completed only if all tests passed and a senior engineer approved the change.
AI Coding Agent Results (September to October 2026)
| Rank | Coding Agent | Model Used | Tasks Completed | Avg. Minutes per Task | Avg. Cost per Task |
| 1 | Claude Code | Claude Opus 5.5 | 78.3% | 11.4 | $1.86 |
| 2 | OpenAI Codex | GPT-6.1 Sol | 74.6% | 13.2 | $1.52 |
| 3 | Cursor | Cursor agent (default models) | 71.9% | 9.8 | $1.21 |
| 4 | Gemini CLI | Gemini 4 Argon | 68.8% | 10.6 | $0.88 |
| 5 | GitHub Copilot | Copilot agent (default models) | 66.4% | 12.7 | $0.94 |
| 6 | Grok Build | Grok 4.7 | 63.5% | 8.9 | $0.71 |
| 7 | Windsurf | Cascade agent (default models) | 61.2% | 11.8 | $0.83 |
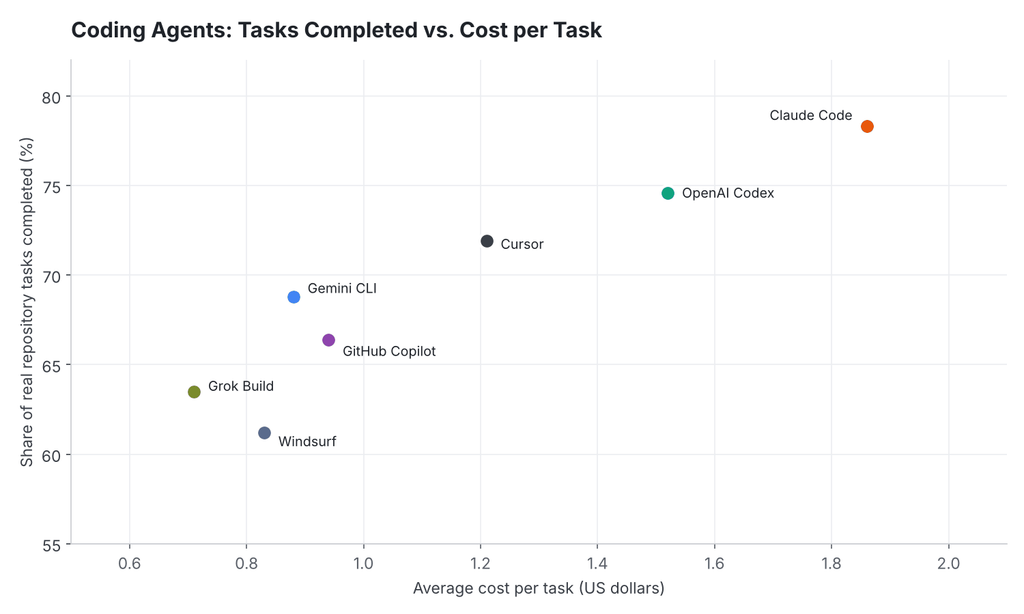
Here is what our team took from the agent results:
- We found that Claude Code completed the most tasks (78.3%), 3.7 points ahead of OpenAI Codex, but it was also the most expensive at $1.86 per task.
- Grok Build was the cheapest agent at $0.71 per task and the fastest at 8.9 minutes, which suits simple, well-defined tasks.
- Cursor completed 71.9% of tasks in an average of 9.8 minutes, the best balance of results and speed among editor-based tools.
Best AI for Vibe Coding
Vibe coding means building software by describing what you want in plain English and letting AI write all of the code. We recruited 24 people with no programming experience and asked them to build the same 60 app ideas, such as a booking page for a hair salon or a budget tracker, using four popular vibe coding tools. An app counted as working if a tester could complete its main task without errors.
Vibe Coding Results by Tool (September to October 2026)
| Vibe Coding Tool | Worked on the First Try | Worked After Three Fix Requests | Avg. Minutes to a Working App | Design Score |
| Lovable | 62.1% | 88.3% | 12.6 | 88.7 |
| Replit | 58.3% | 86.7% | 14.2 | 84.1 |
| Bolt | 54.6% | 81.2% | 11.9 | 83.4 |
| v0 | 51.7% | 79.6% | 9.8 | 87.9 |
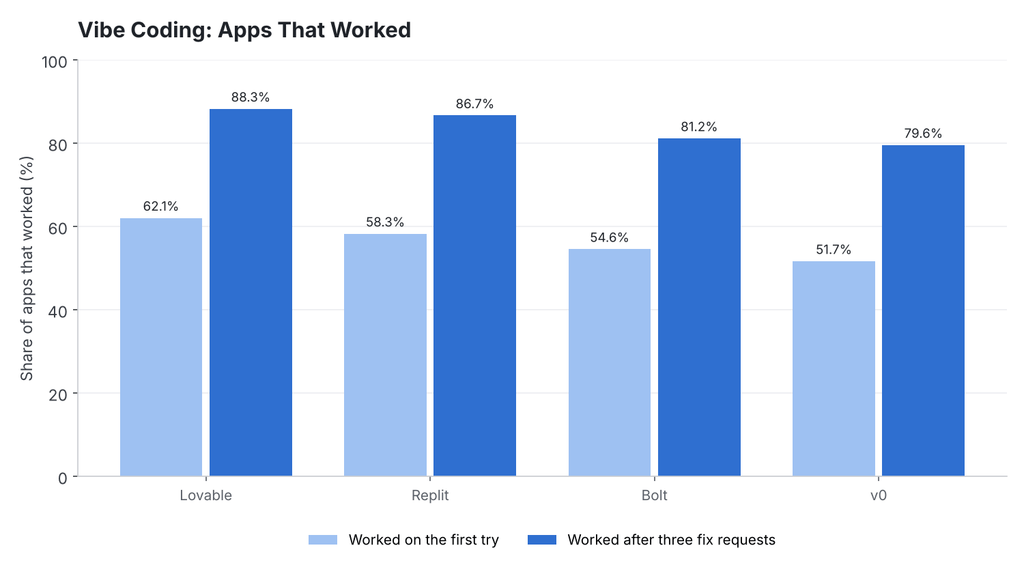
Our researchers drew three conclusions from the vibe coding results:
- We found that Lovable produced the most working apps, 62.1% on the first try and 88.3% after three fix requests, and also earned the top design score (88.7).
- Replit was close behind (86.7% after fixes) and handled apps that needed a database or user accounts best.
- v0 was the fastest, producing a working app in 9.8 minutes on average, and its design score (87.9) was second only to Lovable’s.
Best AI Models for Coding, Including Free Options
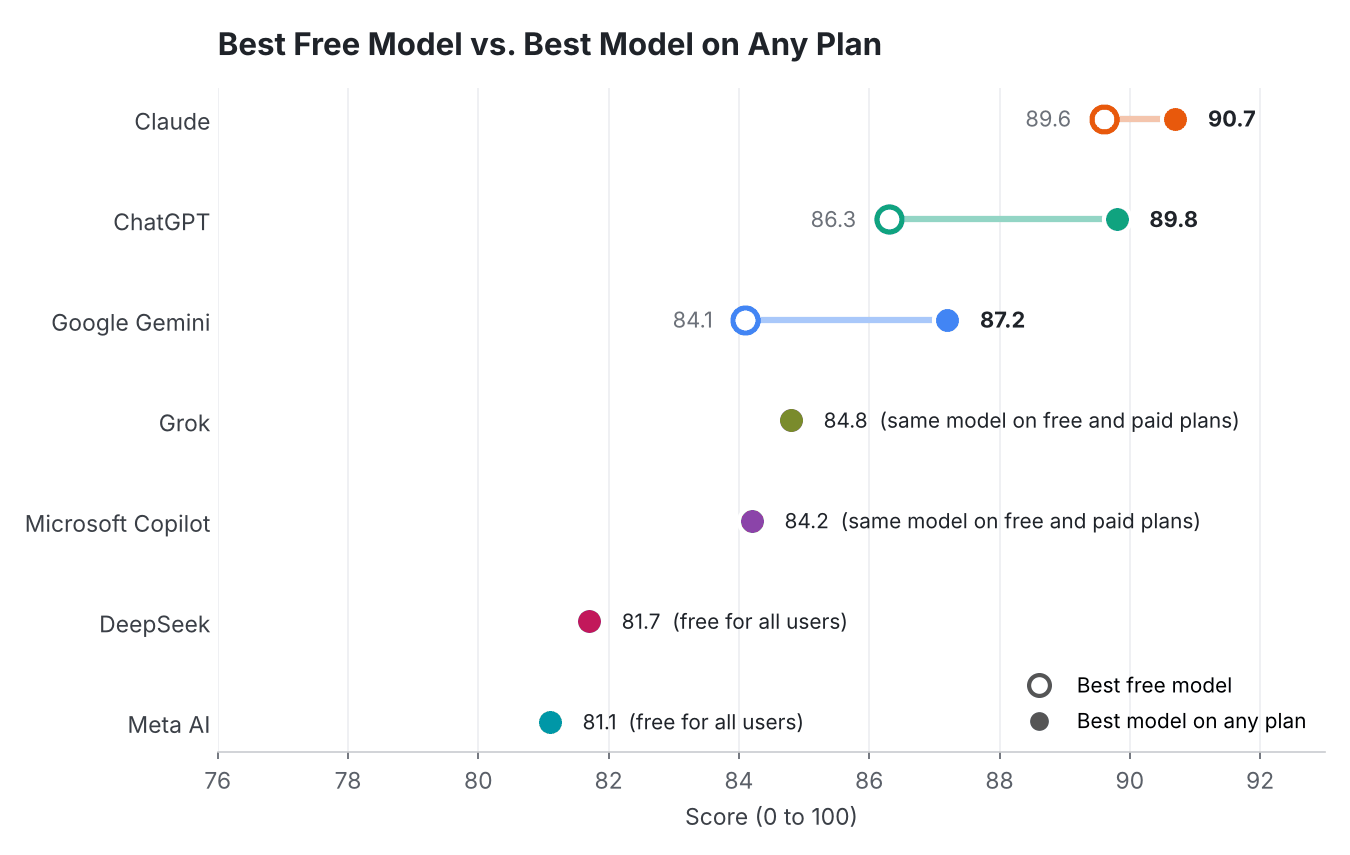
Free users often get a different model than paying subscribers. We tested 10 models across the seven chat platforms, including each platform’s free option. The table below ranks every model we tested.
Coding Scores by Model (September to October 2026)
| Rank | Model | Platform | Available On | Score | First-Try Pass Rate |
| 1 | Claude Opus 5.5 | Claude | Paid | 92.1 | 84.6% |
| 2 | Claude Sonnet 5.5 | Claude | Free and paid | 91.4 | 83.1% |
| 3 | GPT-6 Sol | ChatGPT | Paid | 90.9 | 81.9% |
| 4 | Gemini 4 Argon | Google Gemini | Paid | 89.0 | 78.3% |
| 5 | GPT-6 Luna | ChatGPT | Free and paid | 87.2 | 76.4% |
| 6 | Gemini 3.8 Flash | Google Gemini | Free and paid | 86.4 | 74.1% |
| 7 | Grok 4.6 | Grok | Free and paid | 85.1 | 72.4% |
| 8 | DeepSeek V4-Pro | DeepSeek | Free | 84.2 | 73.8% |
| 9 | GPT-6 Astra | Microsoft Copilot | Free and paid | 83.0 | 69.7% |
| 10 | Muse Spark | Meta AI | Free | 77.5 | 61.2% |
Our team took three main points from the model-level results:
- We found that Claude Sonnet 5.5 is the best free AI for coding, scoring 91.4, higher than every paid model from other platforms.
- Free users of ChatGPT and Gemini gave up more: GPT-6 Luna scored 3.7 points below GPT-6 Sol, and Gemini 3.8 Flash scored 2.6 points below Gemini 4 Argon.
- DeepSeek V4-Pro, which is free for everyone, passed 73.8% of tests on the first try, close to the free GPT-6 Luna (76.4%).
Requesting a Copy of This Report
If you’d like to request a PDF copy of this report or learn more about our agency, you can reach out here.
- First Page Sage Research Study, First Page Sage, September to October 2026, San Francisco, California
- Introducing Claude Sonnet 5.5, Anthropic, September 2026, San Francisco, California
- ChatGPT Release Notes, OpenAI, October 2026, San Francisco, California
- Google Releases Gemini 4 Argon, Called Its Most Powerful Model Yet, TechCrunch, September 2026, San Francisco, California