Last updated November 2, 2026
Our research team conducted a study of autonomous AI agents, covering how they’re used, how widely adopted they are, and where they hold up or fall short. Our original study began on January 14, 2025, and we’ve subsequently updated it to include data up through October 27, 2026.
Monthly active user (MAU) rankings were compiled from founder interviews, first-party published claims, and third-party research. Data on task performance, trust, time efficiency, and satisfaction were collected through a survey of agentic AI users. Source citation counts and refusal rates were recorded by our research team during direct observation of respondents as they completed tasks. The study covers ten general-purpose autonomous agents; coding assistants such as Claude Code, Codex and Cursor are tracked in a separate study. In the sections below, we break down each of these measures across the leading platforms.
The Top Autonomous AI Agents of 2026
In this section, we list the top autonomous AI agents by number of monthly active users as of October 2026. The number of monthly active users is the strongest indicator of user engagement and adoption, and the growth rate of MAUs over time reveals whether a platform is gaining ground or starting to stall. The rankings draw on founder interviews, company-published figures, and outside research covering each platform’s user base. Agents that launched during the study period, Meta Muse in September 2026 and Grok Bot in August 2026, are ranked on their October 2026 users and carry no quarterly growth figure.
In the table below, we rank each platform by MAUs, then break down the drivers of its position, from primary applications and underlying model architectures to recent quarterly growth.
Top Autonomous AI Agents, 2026
| Rank | Autonomous AI Agent | Monthly Active Users (October 2026) | Top Use Cases | Model Families Used | Est. Quarterly Growth |
| 1 | Meta Muse | 6.84 million | Sending emails, booking travel, filling out forms, lowering bills, shopping and payments | Muse Spark, Muse Wonder (Meta) | New (launched September 2026) |
| 2 | Manus | 3.41 million | Multi-step research projects, content production, automated workflows, and personal errands through its Cue agents | Multi-model stack led by Claude, plus other frontier and open-source models | +21% |
| 3 | OpenAI Agents (ChatGPT agent + API agents) | 2.97 million | Research and synthesis, file workflows, customer support automation, content and SEO production, internal copilots | GPT | +18% |
| 4 | OpenClaw | 2.49 million | Lead generation and outreach, personal ops automation, cross-tool workflows, autonomous research agents, growth hacking, and scraping | Model-agnostic with support for GPT, Claude, Gemini, DeepSeek, and open-source models | +10% |
| 5 | Claude (computer use, Cowork and Dispatch) | 1.68 million | Desktop and browser tasks, document and spreadsheet work, cross-app workflows, and recurring tasks assigned from a phone | Claude | +27% |
| 6 | Perplexity Computer | 1.04 million | Deep research, market and competitor analysis, quick decision support, learning and education, news monitoring | Multi-model stack with GPT, Claude, Gemini, Grok, PPLX, and open-source models | +15% |
| 7 | Replit Agent | 601,000 | Building full apps from prompts, debugging and fixing code, automating scripts, deploying software, and iterating on MVPs | Multi-model stack with GPT, Claude, Replit, and open-source models | +9% |
| 8 | Devin | 352,000 | End-to-end feature development, large refactors, bug investigation, engineering task delegation, and documentation generation | Proprietary model stack tuned for software engineering | +12% |
| 9 | Grok Bot | 287,000 | Inbox and calendar management, work across the apps it is signed into, and delegated multi-step tasks | Grok | New (beta launched August 2026) |
| 10 | Gemini Agent | 164,000 | Multi-step tasks across Google services, daily planning, and errands | Gemini | +11% |
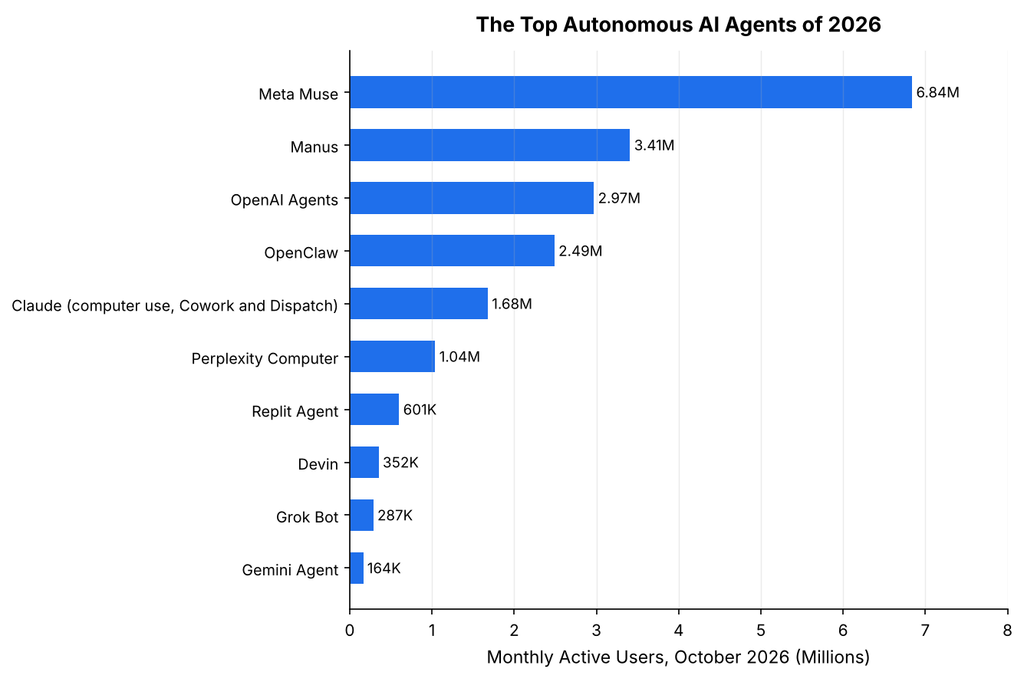
- We found that Meta Muse entered the ranking in first place with 6.84 million MAUs in its first full month after its September 8, 2026 launch, about 2.3 times the 2.97 million for OpenAI Agents and 3.43 million ahead of second-place Manus. Muse launched free on iOS, Android, the web and WhatsApp, which we suspect explains much of how quickly it built an audience, though our dataset cannot isolate the cause. Meta reported in October that Muse had passed 10 million users; our figure counts only people active during the month.
- Our data showed the fastest estimated quarterly growth among established platforms at Claude (+27%), whose computer use, Cowork and Dispatch features let it work across a user’s desktop and apps, followed by Manus (+21%), which became independent on September 1, 2026, launched Manus 2.0 and its Cue personal agents on September 28, and raised more than $500 million in October. OpenAI Agents (+18%) and Perplexity Computer (+15%) continued to grow as both widened access, while OpenClaw (+10%), Replit Agent (+9%) and Devin (+12%) grew from more established or developer-focused bases.
- We found that gated launches rank low regardless of attention. Grok Bot, the first joint product of SpaceXAI and Cursor, reached 287,000 MAUs while its beta remains limited to SuperGrok Heavy, Cursor Ultra and Cursor Teams Premium subscribers, and Gemini Agent, available only to Google AI Ultra subscribers in the U.S., reached 164,000.
Task Performance and Completion Rates
To assess how effectively each agentic AI platform handled complex, multi-step workflows, we conducted a performance evaluation. The research focused on the platforms with general-purpose, autonomous task execution and a large enough user base to yield reliable task-level data, including Devin, OpenClaw, Claude, Manus, OpenAI Agents, Gemini Agent, Meta Muse, Replit Agent, Grok Bot, and Perplexity Computer. Meta Muse and Grok Bot entered our observation panel when they launched, so their rates rest on fewer observed tasks than the other platforms’ rates.
In the table below, we show the share of multi-step tasks each platform completed without a person stepping in, pooled across the full study window.
Task Performance and Completion Rates, 2026
| Rank | Platform | Task Completion Rate |
| 1 | Devin | 85.2% |
| 2 | OpenClaw | 80.3% |
| 3 | Claude | 79.4% |
| 4 | Manus | 77.6% |
| 5 | OpenAI Agents | 74.4% |
| 6 | Gemini Agent | 72.5% |
| 7 | Meta Muse | 71.8% |
| 8 | Replit Agent | 70.2% |
| 9 | Grok Bot | 69.3% |
| 10 | Perplexity Computer | 66.6% |
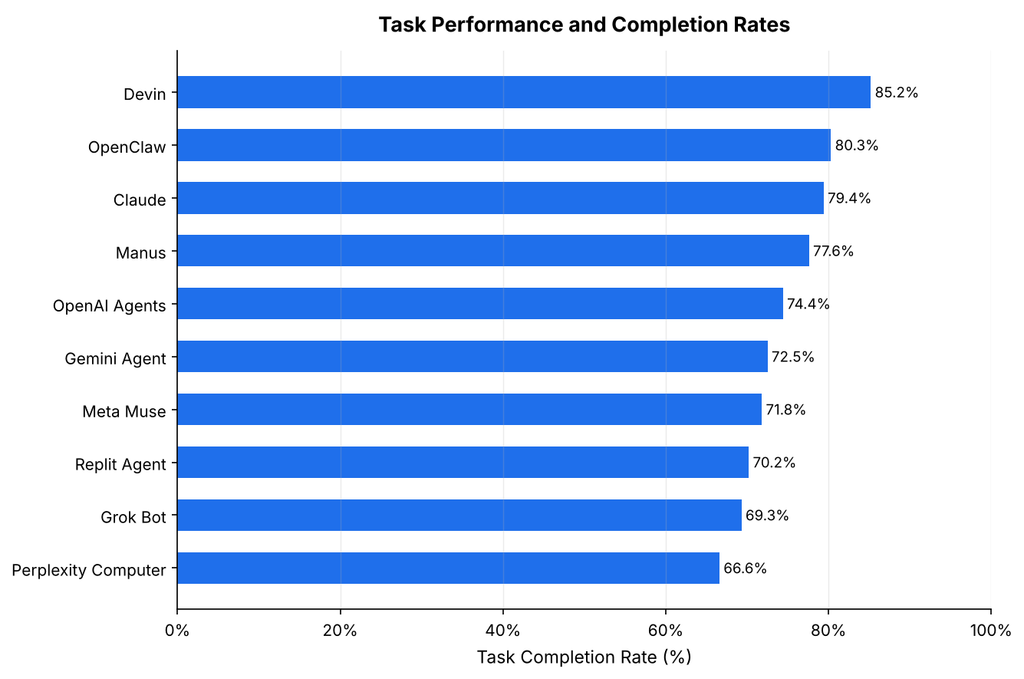
- The mean completion rate across the ten platforms was 74.7%, which indicates one in four multi-step tasks still needed a person to step in. Devin led at 85.2%, followed by OpenClaw (80.3%) and Claude (79.4%), and Perplexity Computer recorded the lowest rate at 66.6%, an 18.6-point gap from first to last.
- We attribute most of that spread to task scope. Devin works almost entirely on software engineering tasks inside a codebase, where success can be checked by running tests. Meta Muse (71.8%) and Grok Bot (69.3%) take on errands and workflows that end in a purchase, a submitted form or a sent message, where a missing detail or a required approval stops the task, and Perplexity Computer and OpenAI Agents take on open-ended research with no built-in check for a correct result.
- Completion rate did not track with popularity in our data. Meta Muse has the largest user base and placed seventh, while Devin, eighth by users, placed first. Many users appear to choose general-purpose agents for their range and accept a lower finish rate in exchange, which suggests reliability will arrive first in narrow domains with verifiable outcomes, with coding as the clearest example.
Research Depth: Sources Per Task
To assess whether AI agents serve as a viable substitute for genuine research, our team directly observed and recorded the number of sources each platform cited for each task, noting the minimum and maximum across the entire study. Meta Muse and Grok Bot were observed from their launch dates.
In the table below, we list each platform’s observed range of sources cited per task, along with what shapes that count, from whether it searches the open web to whether it sticks to local files and uploads.
Research Depth: Sources Per Task, 2026
| Platform | Minimum Sources Per Task | Maximum Sources Per Task | Notes |
| Manus | 3 | 18 | Runs its own browser and cloud computer, searching widely and pulling in outside documents across long research tasks. |
| OpenClaw | 3 | 16 | Runs its own web searches and pulls in outside resources as it works through a task. |
| Claude | 2 | 12 | Combines connectors, browser navigation and on-screen control, drawing sources from both the web and the user’s own apps. |
| Gemini Agent | 2 | 10 | Draws on Google Search alongside the user’s Gmail, Calendar and Drive. |
| Grok Bot | 2 | 9 | Works across the apps it is signed into, using web search mainly to confirm details. |
| Replit Agent | 2 | 8 | Pulls information by crawling and reading through multiple web pages. |
| Perplexity Computer | 2 | 8 | Can take in images and audio alongside text to build context for a task. |
| Meta Muse | 1 | 6 | Focuses on completing errands, consulting only the few sites needed to book, fill out a form or buy. |
| Devin | 1 | 4 | Sticks mostly to local files and applications, and only goes online when told to. |
| OpenAI Agents | 1 | 4 | Works from files the user uploads directly, with browsing available only if it’s turned on. |
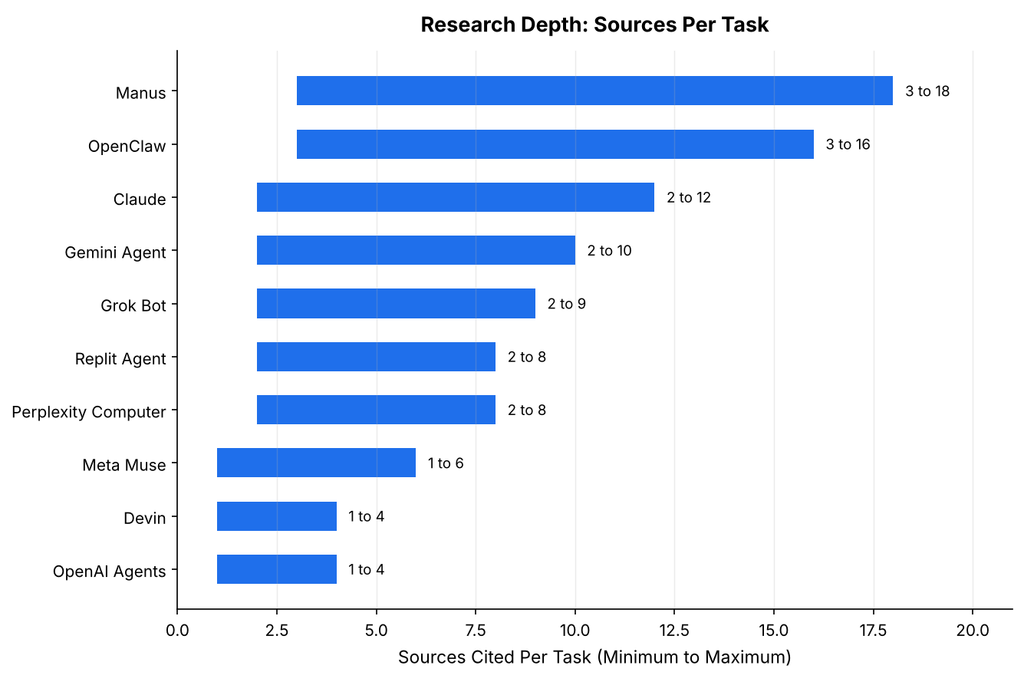
Because these figures are the minimum and maximum observed across every task in the study, the ranges can only widen as the dataset grows. Manus’s ceiling of 18 sources is the widest in the study, ahead of OpenClaw’s 16 and more than double the 8-source maximum recorded for Replit Agent and Perplexity Computer, while no platform’s floor exceeded 3 sources. The data suggests that platforms designed to actively search the web and external resources draw from a wider variety of sources in an average task. By contrast, those focused on local files, code, uploaded documents or completing errands, such as Meta Muse at a maximum of 6, drew from fewer, regardless of overall user base size.
Trust Gap Between Agentic and Manual Search
When people turn to AI agents for search and discovery, confidence in the results matters just as much as getting them quickly. We asked users to score their trust in manual results versus agentic results for the same tasks.
In the table below, we show which set of results respondents trusted more, pooled across all survey waves.
Trust Gap Between Agentic and Manual Search, 2026
| Preferred Results | Share of Respondents |
| Manual Search Results | 53.5% |
| Agentic Results | 33.7% |
| No Preference | 12.8% |
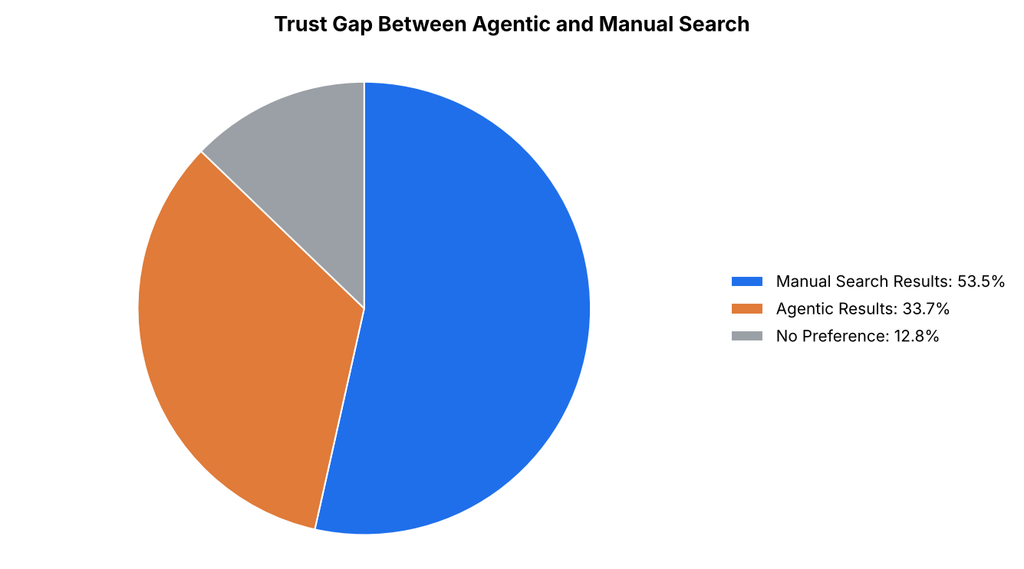
Manual search results remained significantly more trusted, with 53.5% of respondents preferring them over agentic results, compared with 33.7% who trusted the agentic output more. That 19.8-point gap is the clearest sign in our dataset that speed has not yet translated into confidence. We suspect many of the 12.8% with no preference verify agentic output against a manual check regardless, though our survey did not ask respondents to confirm this.
Time Efficiency of Agentic Tools
Businesses and individuals alike tend to adopt agentic tools for one main reason: time saved. We asked users to perform a range of tasks, both manually and with an AI agent, and compared the time spent to gauge the current state of agentic tools.
In the table below, we break down average minutes per task with and without an agent across specific applications, ranging from trip planning and budget optimization to B2B vendor sourcing.
Time Efficiency of Agentic Tools, 2026
| Task Type | Minutes With an AI Agent | Minutes Manual | Time Saved (%) |
| Trip Planning | 9.2 | 38.7 | 76% |
| Budget Optimization | 6.1 | 21.5 | 72% |
| SaaS Comparative Analysis | 7.9 | 27.2 | 71% |
| Learning Recommendations | 5.2 | 14.6 | 64% |
| B2B Vendor Sourcing | 10.0 | 22.4 | 55% |
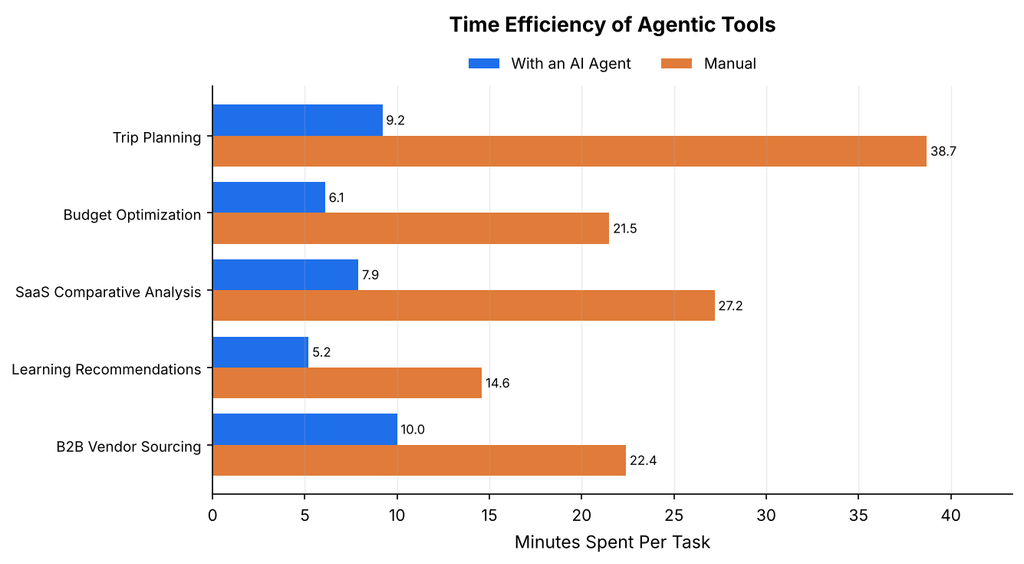
- We found that the average time savings across all five tasks when using an AI agent versus completing the task manually was 67.6%, one of the more measurable outcomes of agentic AI.
- Trip planning showed the largest savings (76%), cutting an average of 29.5 minutes per task, while B2B vendor sourcing showed the smallest (55%) and was also the slowest task to complete with an agent at 10.0 minutes.
- Our data showed smaller savings on tasks that demand more vetting. Vendor sourcing and learning recommendations require users to check the agent’s picks against their own criteria, and we suspect that review consumes part of the time the agent saved.
Most-Refused Agentic Task Types
High task refusal rates pose a significant barrier to the adoption of agentic AI tools and, conversely, underscore the ongoing need for additional human involvement in industries such as law and medicine.
Our study found that approximately 9% of user requests were rejected outright by agentic platforms. The most common reasons involved ethical concerns, insufficient information, or speculative content. In the table below, we share the task types refused most often, their refusal rates, and the reasoning behind each.
Most-Refused Agentic Task Types, 2026
| Task Type | Refusal Rate | Refusal Reason |
| Legal Counsel | 31.7% | Most agents won’t interpret laws or give personalized legal advice, since that can cross into the unauthorized practice of law. |
| Reverse Engineering | 21.2% | Decompiling protected software, reverse engineering another AI’s algorithms, or picking apart proprietary firmware is a hard no for most agents on both ethical and legal grounds. |
| Financial Investment Guidance | 17.8% | Picking stocks or building a personalized investment portfolio is treated as high-risk territory, so most agents steer clear rather than risk offering unlicensed financial advice. |
| Speculative Predictions | 15.1% | Agents tend to avoid predicting market moves, election outcomes, or other future events, since the results are unreliable and overstate what the system can actually do. |
| Health Risk Assessments | 14.2% | Diagnosing a condition or giving personalized medical guidance is off-limits for most systems, largely to stay within HIPAA and FDA rules. |
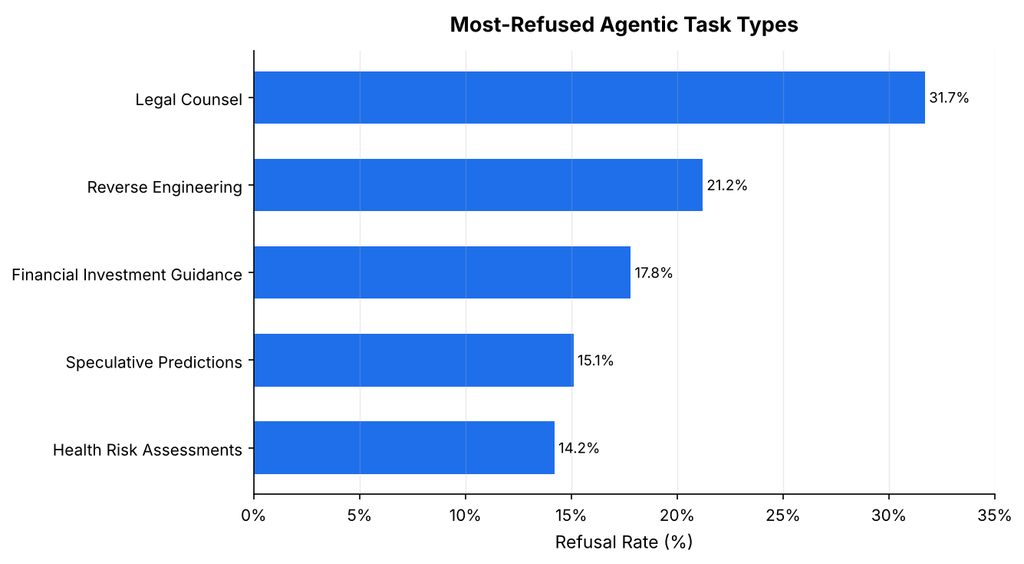
- We found that legal counsel requests were refused at 31.7%, roughly one in three and about 1.5 times the rate for reverse engineering (21.2%), the second most-refused category.
- Our data showed the three regulated advice categories (legal, financial, and health) all landing between 14.2% and 31.7%, well above the roughly 9% refusal rate across all requests.
- Speculative predictions (15.1%) and health risk assessments (14.2%) sit just 0.9 points apart, which suggests agents treat unverifiable forecasts with nearly the same caution as regulated medical guidance.
User Satisfaction by Task Type
We analyzed user satisfaction on a 1-10 scale (1 = very dissatisfied, 10 = very satisfied) for tasks in 6 categories to gauge how effectively AI agents completed different types of tasks.
- Informational tasks ask the agent for straightforward facts or explanations, like a definition or a quick topic overview, where little judgment is required.
- Comparative tasks have the agent weigh two or more items against each other.
- Navigational tasks send the agent into another program or app to complete a subtask there.
- Exploratory tasks are more open-ended, covering brainstorming or general discovery.
- Transactional tasks are where the agent actually completes a purchase or other transaction on the user’s behalf.
- Generative tasks have the agent produce something new, such as a document, image, or block of code.
In the table below, we show the average satisfaction score for each task category, pooled across the full study.
User Satisfaction by Task Type, 2026
| Task Type | Average Satisfaction (1 to 10) |
| Informational | 8.2 |
| Comparative | 7.9 |
| Navigational | 7.6 |
| Exploratory | 7.1 |
| Transactional | 6.5 |
| Generative | 5.8 |
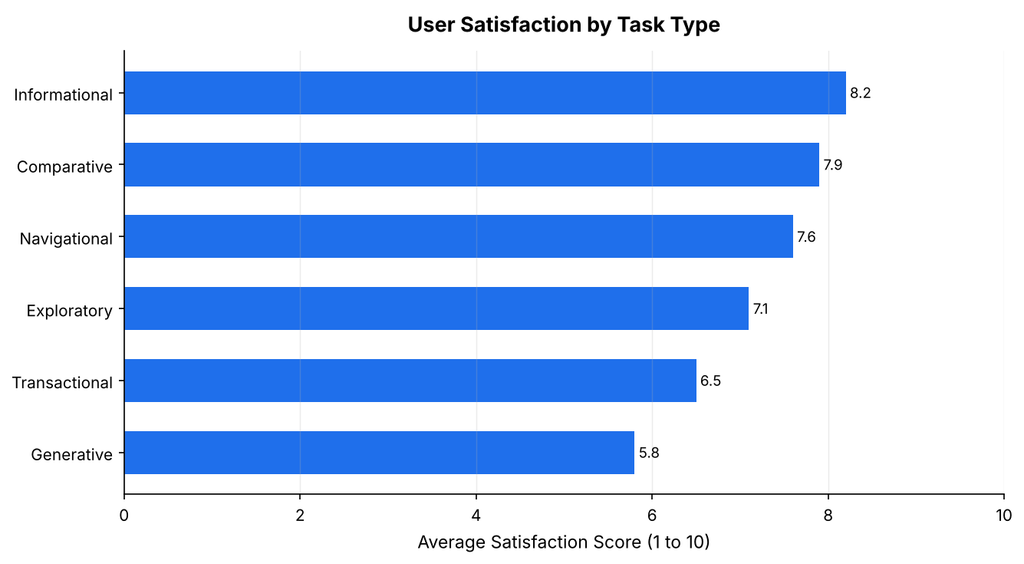
In our study, informational tasks scored highest (8.2), largely because algorithms for basic information discovery have been refined through the widespread use of generative AI chatbots since late 2022. Tasks requiring novel content generation (5.8) and transactions (6.5) scored the lowest due to frequent errors. Transactional scores have edged up as errand-focused agents such as Meta Muse joined the panel, but these systems are still new and haven’t had much time to be trained or fine-tuned for that kind of work.
Taken together, this data points to a technology that’s still finding its footing. Adoption is growing, and the time savings on well-defined tasks are hard to ignore, but trust in agentic results still lags behind trust in manual search, and the refusal rates are still high enough to matter for anyone relying on these tools for legal, financial, or health-related questions. The gap between platforms also comes down to fit, since a system built to browse the open web behaves very differently from one that sticks to local files, and each performs best on the type of task it was designed around. Generative and transactional tasks lag furthest behind, which suggests that the next phase of agentic AI will depend on whether these systems can close that gap.ch suggests that the next phase of agentic AI will depend on whether these systems can close that gap.
Further Reading
- Agentic AI Adoption Statistics for 2026
- Top Generative AI Chatbots by Market Share
- Which Industries Use Generative AI To Make Purchases?
- ChatGPT Usage Statistics
- Generative AI Statistics
Requesting a Copy of This Report
If you’d like to request a PDF copy of this report or learn more about our agency, you can reach out here.