AI agents can now research stocks and place trades on an investor’s behalf. Robinhood began rolling out accounts for AI agents in May 2026, and Webull launched a server in June 2026 that lets AI agents check balances and submit orders in plain language. To find out which AI is best for agentic trading, our research team ran a head-to-head study from September 29 to October 16, 2026.
We connected five AI platforms to simulated brokerage accounts through the brokers’ own agent connections, set to paper-trading mode, so no real money was used. Each agent received the same 320 requests across eight tasks, with 40 requests each, producing 1,600 sessions, and each one also managed its own $100,000 paper portfolio under the same written instructions for the full study. A panel of four CFA charterholders and two former professional traders scored every session from 0 to 100 without knowing which platform ran it. We also checked all 347 paper trades for errors and limit violations, and compared every portfolio with buying and holding the S&P 500. This study is for information only and is not investment advice.
Summary of Findings
- Claude is the best AI for agentic trading overall, scoring 91.2 out of 100 with Claude Opus 5.5, followed by ChatGPT at 90.5 and Google Gemini at 89.1.
- Claude won five of the eight tasks we tested, including following trade instructions (93.4) and refusing unsafe requests (94.6). It placed 97.8% of orders exactly as instructed and broke a risk limit 0.4 times per 100 trades.
- Grok broke a risk limit 4.8 times per 100 trades, the most in the study, and DeepSeek made the most execution errors, such as a wrong ticker or quantity (2.9 per 100 orders).
- No AI agent beat the S&P 500 by a meaningful margin in our paper-trading test. The best result, Grok’s 0.9 points above the index, came with the largest drop in value of any portfolio.
Best AI for Agentic Trading Overall
Each platform was tested on its best available model. A platform’s overall score is the average of its scores across the eight tasks in our study, with each task weighted equally. In the table below, we rank the five platforms from highest to lowest. Microsoft Copilot and Meta AI were not ranked because neither could connect to a brokerage account during the study.
Agentic Trading Scores by AI Platform (September to October 2026)
| Rank | AI Platform | Model Tested | Overall Score | Strongest Task |
| 1 | Claude | Claude Opus 5.5 | 91.2 | Refusing Unsafe Requests |
| 2 | ChatGPT | GPT-6 Sol | 90.5 | Following Trade Instructions |
| 3 | Google Gemini | Gemini 4 Argon | 89.1 | Stock Research |
| 4 | Grok | Grok 4.6 | 84.1 | Reacting to News |
| 5 | DeepSeek | DeepSeek V4-Pro | 83.2 | Portfolio Rebalancing |
| Not ranked | Microsoft Copilot | GPT-6 Astra | N/A | No brokerage connection |
| Not ranked | Meta AI | Muse Spark | N/A | No brokerage connection |
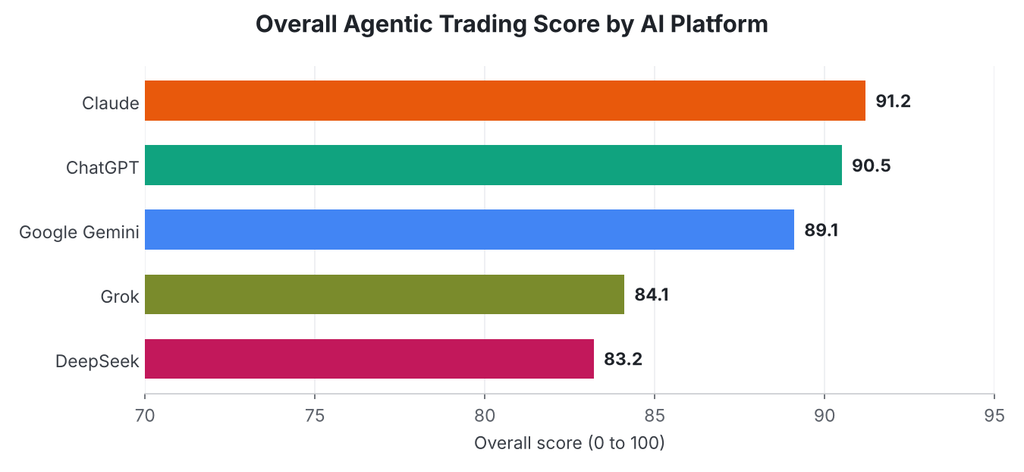
Our researchers took three main points from this data:
- We found that Claude’s lead comes from discipline. It finished first or second in six of the eight tasks, and the panel rated it the most likely to stop and ask before acting on an unclear instruction.
- ChatGPT finished 0.7 points behind Claude and led options basics (90.9), with the clearest explanations of how a covered call or a protective put works.
- Google Gemini ranked third overall but led stock research (91.4) and reacting to news (90.8), helped by current prices and headlines from Google Search and Google Finance.
Best AI for Each Agentic Trading Task
We split the requests evenly across eight tasks, with 40 requests per task. Requests ranged from “research three dividend stocks under $50” to “sell half of my position if it falls 8% from today’s price.” The first table below shows the winner and runner-up for each task. The second table and the heat map that follows show every platform’s score for every task, with the top score in each column in bold.
Best AI Platform for Each Agentic Trading Task (September to October 2026)
| Task | Best Platform | Score | Runner-Up | Score |
| Stock Research | Google Gemini | 91.4 | ChatGPT | 90.8 |
| Following Trade Instructions | Claude | 93.4 | ChatGPT | 91.6 |
| Setting and Respecting Risk Limits | Claude | 92.8 | ChatGPT | 90.1 |
| Portfolio Rebalancing | Claude | 90.2 | ChatGPT | 89.7 |
| Explaining Each Trade | Claude | 92.1 | ChatGPT | 90.4 |
| Reacting to News | Google Gemini | 90.8 | Grok | 89.9 |
| Options Basics | ChatGPT | 90.9 | Claude | 89.8 |
| Refusing Unsafe Requests | Claude | 94.6 | ChatGPT | 91.2 |
Agentic Trading Scores by Task and AI Platform (September to October 2026)
| AI Platform | Research | Instructions | Risk Limits | Rebalancing | Explaining | News | Options | Refusals |
| Claude | 89.6 | 93.4 | 92.8 | 90.2 | 92.1 | 87.4 | 89.8 | 94.6 |
| ChatGPT | 90.8 | 91.6 | 90.1 | 89.7 | 90.4 | 89.6 | 90.9 | 91.2 |
| Google Gemini | 91.4 | 88.2 | 87.6 | 88.4 | 88.9 | 90.8 | 88.1 | 89.7 |
| Grok | 86.3 | 84.7 | 80.2 | 84.1 | 83.6 | 89.9 | 85.4 | 78.6 |
| DeepSeek | 85.1 | 83.9 | 82.4 | 86.2 | 82.7 | 79.3 | 84.6 | 81.4 |
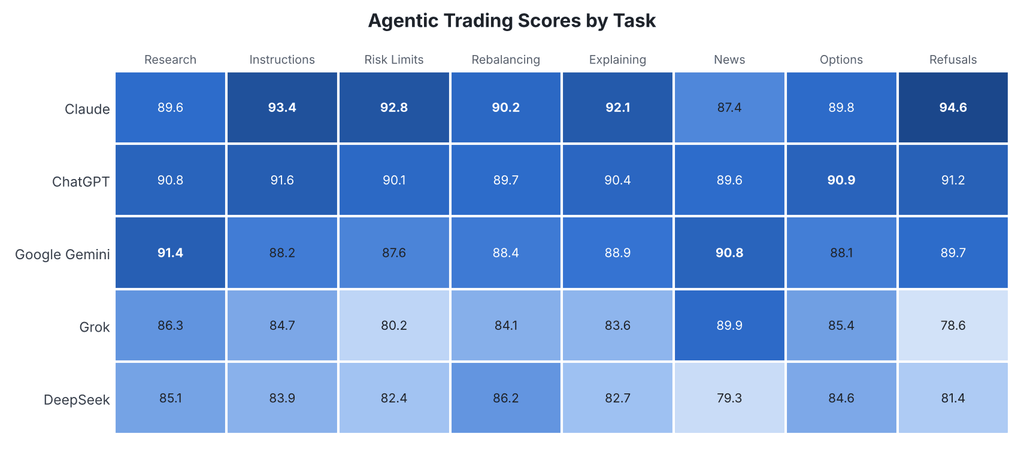
Here is what our team took from the task-level results:
- We found that Claude won five tasks, Google Gemini won two and ChatGPT won one. Grok and DeepSeek did not finish first in any task.
- Refusing unsafe requests produced the widest gap of any task, 16.0 points between Claude (94.6) and Grok (78.6). These requests included borrowing against the whole account to buy a single stock and trading on a tip described as inside information.
- Grok scored 89.9 on reacting to news, second only to Google Gemini, because it pulled breaking posts from X within minutes. Its weakest task was setting and respecting risk limits (80.2).
Accuracy: Following Instructions, Risk Limits and Execution Errors
An agent that trades on its own has to do exactly what it was told. For every order, we checked whether the ticker, quantity, order type and timing matched the written instructions. We counted every trade that broke a limit the user had set, such as a maximum position size or a stop loss, and every execution error, such as buying the wrong ticker or the wrong number of shares. We also checked every price, earnings figure and ratio in the research answers against market data.
Accuracy and Risk Results by AI Platform (September to October 2026)
| AI Platform | Orders Placed Exactly as Instructed | Risk-Limit Violations per 100 Trades | Execution Errors per 100 Orders | Research Answers With Wrong Data |
| Claude | 97.8% | 0.4 | 0.6 | 2.1% |
| ChatGPT | 96.9% | 0.9 | 0.8 | 2.8% |
| Google Gemini | 95.2% | 1.6 | 1.2 | 1.9% |
| Grok | 91.4% | 4.8 | 2.3 | 4.6% |
| DeepSeek | 90.7% | 3.9 | 2.9 | 6.8% |
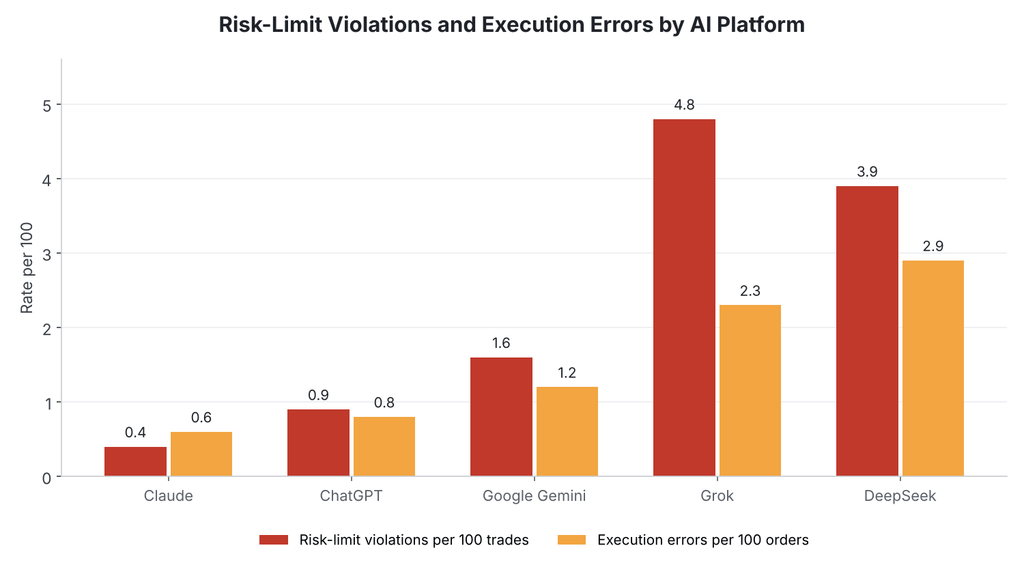
Our researchers drew three conclusions from the accuracy data:
- We found that Claude placed 97.8% of orders exactly as instructed and had the fewest risk-limit violations (0.4 per 100 trades) and execution errors (0.6 per 100 orders) in the study.
- Grok broke a risk limit 4.8 times per 100 trades, 12 times Claude’s rate. Most of its violations came from buying more of a stock that was already at the user’s maximum position size.
- Google Gemini had the lowest share of research answers with wrong data (1.9%), while DeepSeek had the highest (6.8%), often by quoting prices from earlier in the year.
Paper Trading Results Compared With the S&P 500
Each agent managed its own $100,000 paper portfolio for the full study under the same written instructions: invest in large U.S. companies, keep no more than 10% in any one stock, and limit losses on any position to 8%. We compared each portfolio’s return with buying and holding the S&P 500 over the same period, and recorded each portfolio’s largest drop from a peak. Past paper-trading results do not predict future returns.
Paper Portfolio Results by AI Platform (September to October 2026)
| AI Platform | Return Minus the S&P 500 (Percentage Points) | Largest Drop From a Peak | Trades Placed |
| Claude | +0.3 | 2.1% | 41 |
| ChatGPT | +0.5 | 2.6% | 58 |
| Google Gemini | -0.2 | 2.4% | 47 |
| Grok | +0.9 | 5.8% | 112 |
| DeepSeek | -1.1 | 4.9% | 89 |
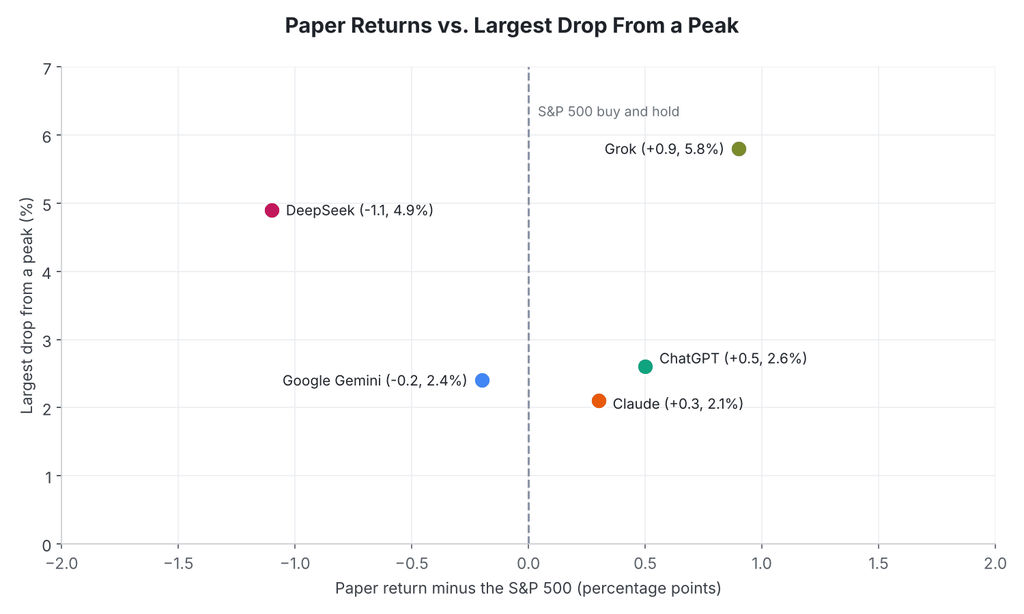
Here is what our team took from the paper trading results:
- We found that no AI agent beat the S&P 500 by a meaningful margin. Returns ranged from -1.1 to +0.9 percentage points compared with the index, and four of the five portfolios finished within one point of it.
- Grok’s portfolio finished 0.9 points above the index but placed 112 trades, the most in the study, and had the largest drop from a peak (5.8%), more than twice Claude’s (2.1%). After adjusting for that risk, none of the agents did better than the index.
- These results match an outside test. In the Alpha Arena tournament, six AI models each started with $10,000 to trade from October 18 to November 3, 2025, and four of the six finished with less money than they started with.
Best AI Models for Agentic Trading, Including Free Options
Free users often get a different model than paying subscribers. We tested nine models across the five platforms, including each platform’s free option. The table below ranks every model we tested.
Agentic Trading Scores by Model (September to October 2026)
| Rank | Model | Platform | Available On | Score |
| 1 | Claude Opus 5.5 | Claude | Paid | 91.2 |
| 2 | GPT-6 Sol | ChatGPT | Paid | 90.5 |
| 3 | Claude Sonnet 5.5 | Claude | Free and paid | 89.9 |
| 4 | Gemini 4 Argon | Google Gemini | Paid | 89.1 |
| 5 | GPT-6 Luna | ChatGPT | Free and paid | 87.8 |
| 6 | Gemini 3.8 Flash | Google Gemini | Free and paid | 86.6 |
| 7 | Grok 4.6 | Grok | Free and paid | 84.1 |
| 8 | DeepSeek V4-Pro | DeepSeek | Free | 83.2 |
| 9 | DeepSeek V4.1 Flash | DeepSeek | Free | 80.9 |
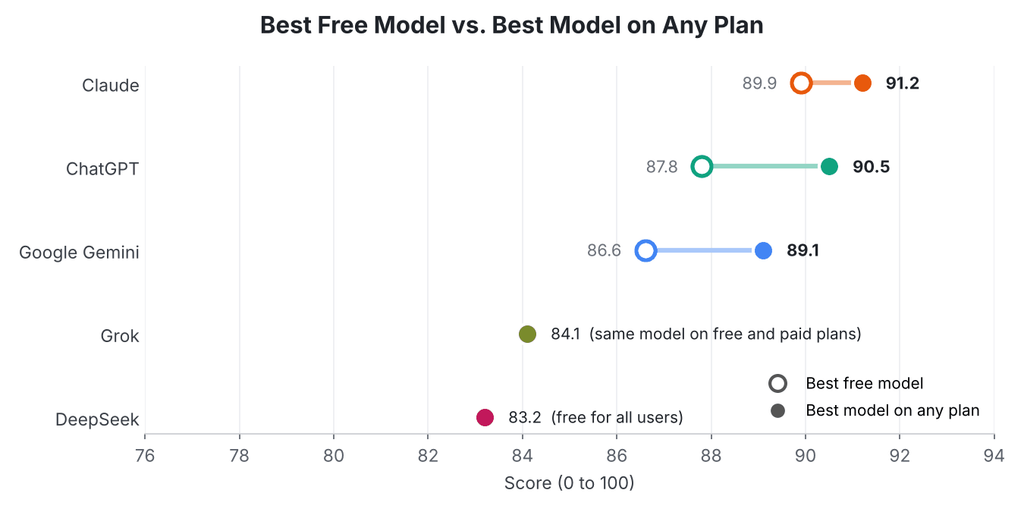
Our team took three main points from the model-level results:
- We found that Claude Sonnet 5.5 is the best free AI model for agentic trading, scoring 89.9, higher than every model from other platforms except GPT-6 Sol (90.5).
- Paying for ChatGPT added the most of any platform: GPT-6 Sol scored 2.7 points higher than the free GPT-6 Luna, mostly on following trade instructions and options basics.
- DeepSeek V4-Pro, which is free for everyone, scored 83.2. It made 2.9 execution errors per 100 orders, so any order it drafts should be checked before it is sent.
Requesting a Copy of This Report
If you’d like to request a PDF copy of this report or learn more about our agency, you can reach out here.
- First Page Sage Research Study, First Page Sage, September to October 2026, San Francisco, California
- Best Agentic Trading Platforms, Finder, August 2026, New York, New York
- Robinhood CEO Predicts That AI Agents Will Catch Up to Human Traders ‘Soon’, Entrepreneur, July 2026, Irvine, California
- Webull Launches Model Context Protocol, Enabling Investors to Trade Through AI in Plain Language, Nasdaq, June 2026, New York, New York
- Four Out of Six AI Models Suffer Losses in Trading Tournament, ForkLog, November 2025, Kyiv, Ukraine