Executives, founders and consultants now ask AI to size markets, sketch pricing and draft board memos, and every major chatbot has added a research mode that reads dozens of web pages before it answers. The risk is that a confident answer rests on numbers nobody can find: an April 2026 University of Pennsylvania study found that deep research agents cited links with no record of ever existing in 10.7% of cases, more than twice the rate of standard search-enabled chatbots. To find out which AI is best for business strategy, our research team ran a head-to-head study from September 29 to October 16, 2026.
We gave the same 480 strategy requests to seven AI platforms, producing 3,360 answers. The requests covered eight strategy tasks, with 60 requests each, built around 40 real companies across software, consumer goods, healthcare, manufacturing and financial services. Each platform was tested in its research mode where it offered one. A panel of six judges, including former management consultants, corporate strategy leaders and venture capital investors, scored every answer from 0 to 100 without knowing which platform wrote it. We also checked every statistic and source each answer cited, and rated whether its recommendations were specific enough to act on.
Summary of Findings
- Claude is the best AI for business strategy overall, scoring 91.0 out of 100 with Claude Opus 5.5 and Research, followed by ChatGPT at 90.3 and Google Gemini at 88.5.
- Claude won five of the eight tasks, including board and investor memos (92.8) and SWOT and scenario planning (92.3). ChatGPT led market sizing (91.8), competitor analysis and financial projections.
- Claude included an invented statistic or source in 3.1% of answers, the lowest rate in the study, while Meta AI did so in 12.8%.
- Research modes raised every platform’s score, by up to 2.2 points, but Grok’s DeepSearch cited links that did not work or did not support the claim 11.2% of the time.
Best AI for Business Strategy Overall
A platform’s overall score is the average of its scores across the eight strategy tasks in our study, with each task weighted equally. In the table below, we rank the seven platforms from highest to lowest.
Business Strategy Scores by AI Platform (2026)
| Rank | AI Platform | Mode Tested | Overall Score | Strongest Task |
| 1 | Claude | Claude Opus 5.5 with Research | 91.0 | Board and Investor Memos |
| 2 | ChatGPT | GPT-6 Sol with deep research | 90.3 | Market Sizing |
| 3 | Google Gemini | Gemini 4 Argon with Deep Research | 88.5 | Market Sizing |
| 4 | Microsoft Copilot | Researcher agent (GPT-6 Astra) | 86.0 | Financial Projections |
| 5 | Grok | Grok 4.6 with DeepSearch | 83.3 | Competitor Analysis |
| 6 | DeepSeek | DeepSeek V4-Pro with search | 81.9 | Financial Projections |
| 7 | Meta AI | Muse Spark | 79.7 | Go-to-Market Plans |
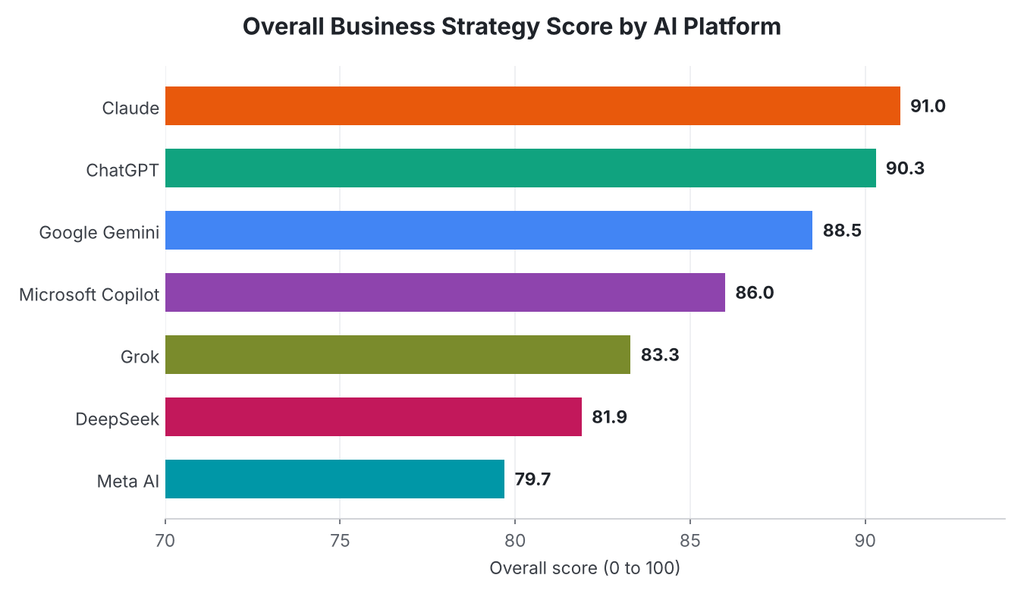
Our researchers took three main points from this data:
- We found that Claude and ChatGPT are close at the top, separated by 0.7 points. The two platforms finished first or second in seven of the eight tasks.
- Claude’s lead came from judgment-heavy work. Judges said its go-to-market plans, SWOT analyses and memos weighed trade-offs most clearly and ended with a firm recommendation. Its weakest task was market sizing (89.6).
- Google Gemini ranked third and placed second in market sizing (90.4), but it did not finish first in any task.
Best AI for Each Business Strategy Task
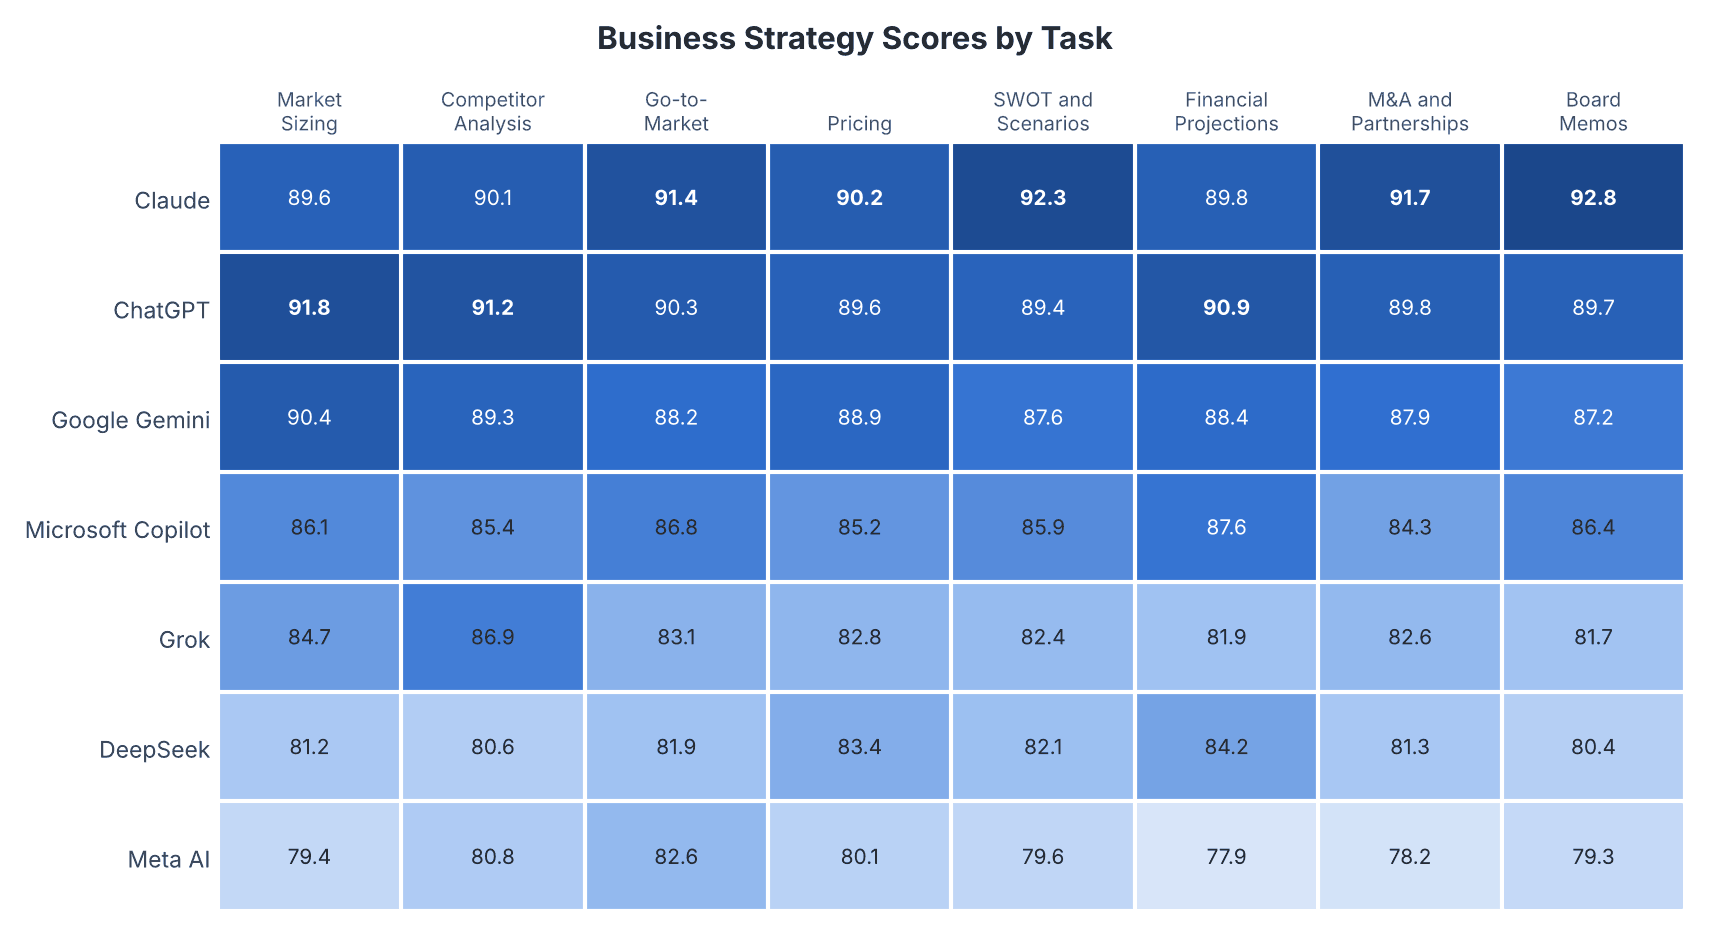
We split the requests evenly across eight strategy tasks, with 60 requests per task. The first table below shows the winner and runner-up for each task. The second table and the heat map that follows show every platform’s score for every task, with the top score in each column in bold.
Best AI Platform for Each Strategy Task (2026)
| Strategy Task | Best Platform | Score | Runner-Up | Score |
| Market Sizing | ChatGPT | 91.8 | Google Gemini | 90.4 |
| Competitor Analysis | ChatGPT | 91.2 | Claude | 90.1 |
| Go-to-Market Plans | Claude | 91.4 | ChatGPT | 90.3 |
| Pricing Strategy | Claude | 90.2 | ChatGPT | 89.6 |
| SWOT and Scenario Planning | Claude | 92.3 | ChatGPT | 89.4 |
| Financial Projections | ChatGPT | 90.9 | Claude | 89.8 |
| M&A and Partnership Evaluation | Claude | 91.7 | ChatGPT | 89.8 |
| Board and Investor Memos | Claude | 92.8 | ChatGPT | 89.7 |
Business Strategy Scores by Task and AI Platform (2026)
| AI Platform | Market Sizing | Competitors | Go-to-Market | Pricing | SWOT | Projections | M&A | Board Memos |
| Claude | 89.6 | 90.1 | 91.4 | 90.2 | 92.3 | 89.8 | 91.7 | 92.8 |
| ChatGPT | 91.8 | 91.2 | 90.3 | 89.6 | 89.4 | 90.9 | 89.8 | 89.7 |
| Google Gemini | 90.4 | 89.3 | 88.2 | 88.9 | 87.6 | 88.4 | 87.9 | 87.2 |
| Microsoft Copilot | 86.1 | 85.4 | 86.8 | 85.2 | 85.9 | 87.6 | 84.3 | 86.4 |
| Grok | 84.7 | 86.9 | 83.1 | 82.8 | 82.4 | 81.9 | 82.6 | 81.7 |
| DeepSeek | 81.2 | 80.6 | 81.9 | 83.4 | 82.1 | 84.2 | 81.3 | 80.4 |
| Meta AI | 79.4 | 80.8 | 82.6 | 80.1 | 79.6 | 77.9 | 78.2 | 79.3 |
Here is what our team took from the task-level results:
- We found that Claude won five tasks and ChatGPT won three. No other platform finished first in any task.
- ChatGPT led the most data-heavy tasks: market sizing (91.8), competitor analysis (91.2) and financial projections (90.9). Its deep research reports pulled in the most company filings and industry reports.
- M&A and partnership evaluation produced the widest gap of any task, 13.5 points between the best and worst platform. Microsoft Copilot scored 87.6 on financial projections, fourth in that task, helped by its Excel output.
Accuracy: Invented Statistics, Citations and Actionable Advice
A strategy is only as good as the facts under it. We checked every statistic in every answer, such as a market size or a competitor’s revenue, against the source it cited or against public filings and industry data. We also opened every cited source to confirm it existed and supported the claim, and our panel rated whether each set of recommendations was specific enough for a team to act on. The table below is sorted from the fewest to the most invented statistics.
Accuracy of AI Business Strategy Answers (2026)
| AI Platform | Answers With an Invented Statistic or Source | Citations That Supported the Claim | Recommendations Rated Actionable |
| Claude | 3.1% | 91.4% | 88.6% |
| ChatGPT | 3.8% | 93.2% | 85.1% |
| Microsoft Copilot | 4.6% | 89.8% | 80.9% |
| Google Gemini | 6.9% | 84.7% | 82.4% |
| Grok | 9.4% | 81.3% | 79.2% |
| DeepSeek | 11.7% | 76.4% | 77.8% |
| Meta AI | 12.8% | 73.9% | 74.6% |
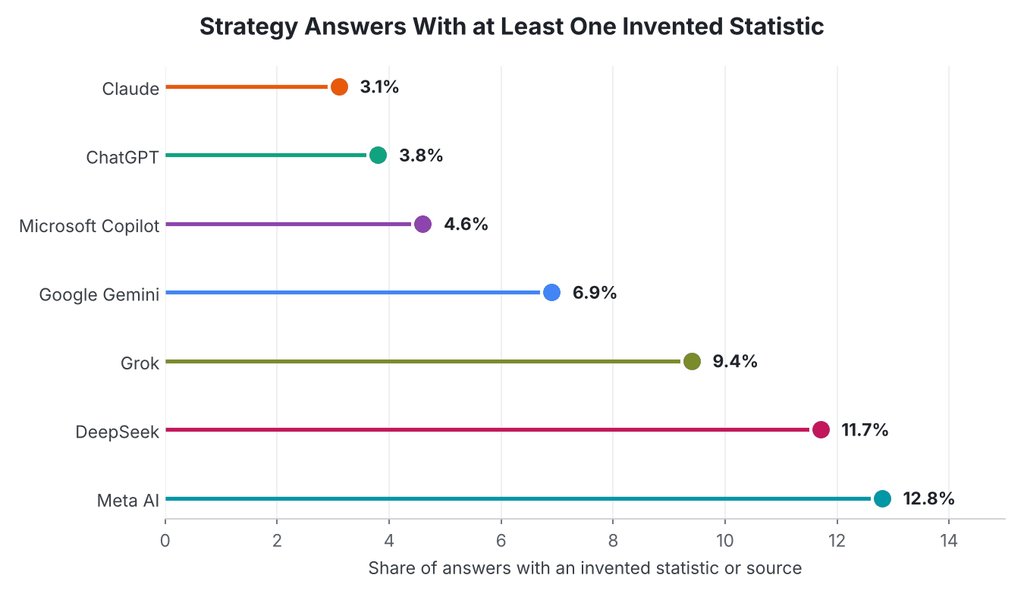
Our researchers drew three conclusions from the accuracy data:
- We found that Claude had the lowest rate of invented statistics (3.1% of answers), followed by ChatGPT (3.8%). Meta AI’s rate of 12.8% was about four times Claude’s.
- ChatGPT had the most reliable citations, with 93.2% of them supporting the claim they were attached to. The most common failure on every platform was a real report cited for a figure it did not contain.
- Claude’s recommendations were rated actionable 88.6% of the time, the highest rate in the study. Judges said its answers set out a next step, an owner and a number to track more often than any other platform’s.
Research Modes vs. Standard Chat
Five of the seven platforms offer a research mode that searches the web for several minutes and returns a long, cited report. We ran the same 480 requests through each platform’s standard chat as well, and compared the two. We did not test a research mode for DeepSeek or Meta AI.
Research Mode vs. Standard Chat Results (2026)
| AI Platform | Research Mode | Standard Chat Score | Research Mode Score | Avg. Minutes per Report | Avg. Sources Cited | Links That Failed or Did Not Support the Claim |
| Claude | Research | 89.2 | 91.0 | 9.8 | 38 | 4.1% |
| ChatGPT | Deep research | 88.1 | 90.3 | 14.6 | 52 | 3.4% |
| Google Gemini | Deep Research | 86.4 | 88.5 | 7.9 | 71 | 9.8% |
| Microsoft Copilot | Researcher agent | 84.4 | 86.0 | 11.2 | 34 | 5.7% |
| Grok | DeepSearch | 81.9 | 83.3 | 3.6 | 46 | 11.2% |
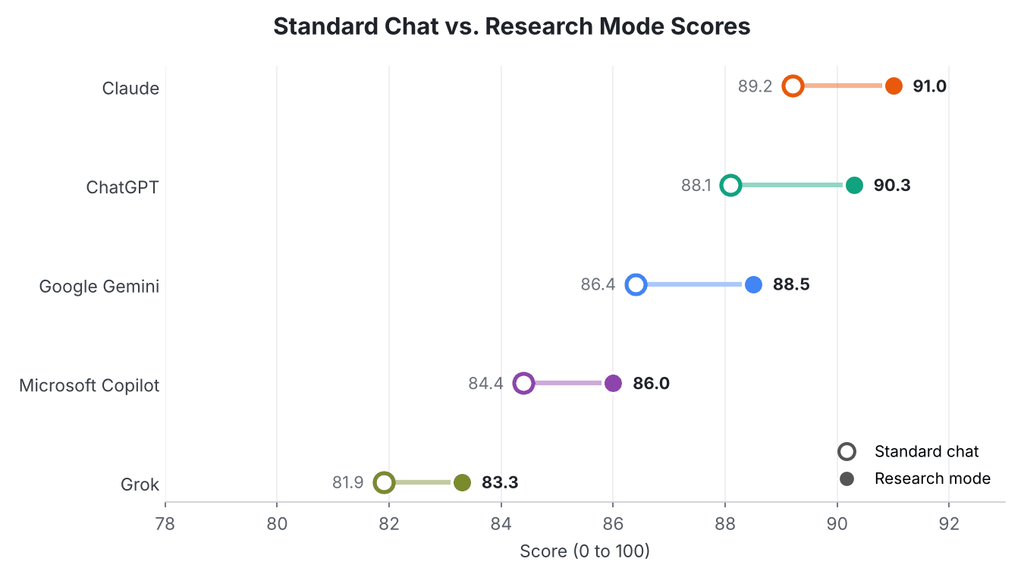
Here is what our team took from the research mode results:
- We found that research modes raised every platform’s score, from 1.4 to 2.2 points. ChatGPT gained the most, and its deep research took the longest at 14.6 minutes per report.
- Google Gemini’s Deep Research cited the most sources, 71 per report, but 9.8% of its links failed or did not support the claim. This matches the University of Pennsylvania finding that citing more sources does not make each citation more reliable.
- Grok’s DeepSearch was the fastest at 3.6 minutes per report but had the highest share of failed or unsupported links (11.2%), so its reports need the most checking before they reach a board.
Best AI Models for Business Strategy, Including Free Options
Research modes and the strongest models are often limited to paid plans. We tested 12 models and modes across the seven platforms, including each platform’s free option. The table below ranks every one we tested.
Business Strategy Scores by Model and Mode (2026)
| Rank | Model or Mode | Platform | Available On | Score |
| 1 | Claude Opus 5.5 (Research) | Claude | Paid | 91.0 |
| 2 | GPT-6 Sol (deep research) | ChatGPT | Paid | 90.3 |
| 3 | Claude Sonnet 5.5 | Claude | Free and paid | 88.7 |
| 4 | Gemini 4 Argon (Deep Research) | Google Gemini | Paid | 88.5 |
| 5 | GPT-6 Luna | ChatGPT | Free and paid | 87.2 |
| 6 | Researcher agent (GPT-6 Astra) | Microsoft Copilot | Paid | 86.0 |
| 7 | Gemini 3.8 Flash | Google Gemini | Free and paid | 85.9 |
| 8 | GPT-6 Astra (standard chat) | Microsoft Copilot | Free and paid | 84.4 |
| 9 | Grok 4.6 | Grok | Free and paid | 83.3 |
| 10 | DeepSeek V4-Pro | DeepSeek | Free | 81.9 |
| 11 | DeepSeek V4.1 Flash | DeepSeek | Free | 80.2 |
| 12 | Muse Spark | Meta AI | Free | 79.7 |
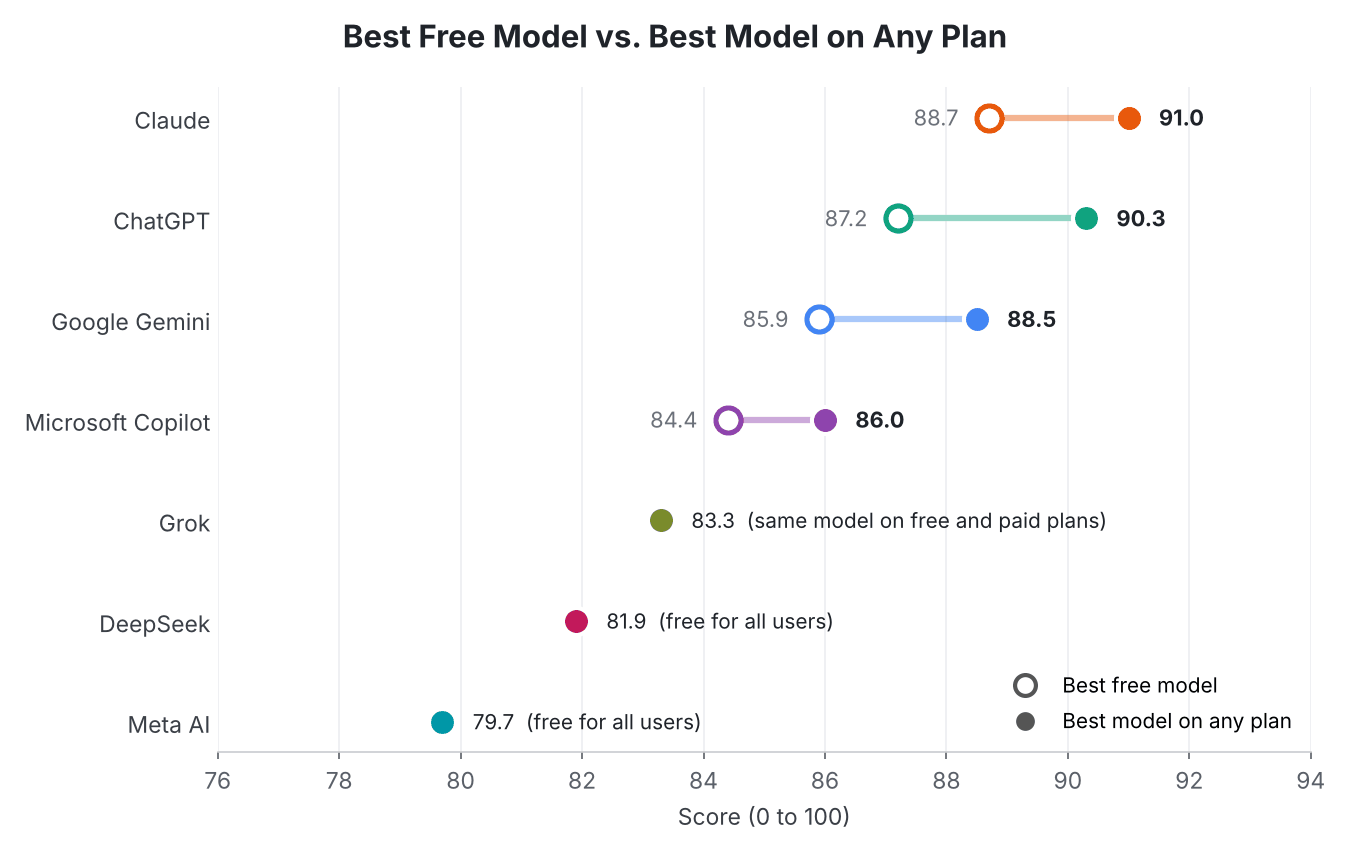
Our team took three main points from the model-level results:
- We found that Claude Sonnet 5.5 is the best free AI for business strategy, scoring 88.7, behind only Claude Opus 5.5 and ChatGPT’s deep research.
- Paying for ChatGPT added 3.1 points over the free GPT-6 Luna, mostly from deep research on market sizing and competitor analysis.
- Microsoft Copilot’s Researcher agent requires a Microsoft 365 Premium plan or a Microsoft 365 Copilot license. On the free plan, Copilot’s standard chat scored 84.4.
Requesting a Copy of This Report
If you’d like to request a PDF copy of this report or learn more about our agency, you can reach out here.
- First Page Sage Research Study, First Page Sage, September to October 2026, San Francisco, California
- Detecting and Correcting Reference Hallucinations in Commercial LLMs and Deep Research Agents, University of Pennsylvania, April 2026, Philadelphia, Pennsylvania
- Get Started With Researcher in Microsoft 365 Copilot, Microsoft, 2026, Redmond, Washington
- ChatGPT Release Notes, OpenAI, October 2026, San Francisco, California
- Gemini Apps Release Updates and Improvements, Google, October 2026, Mountain View, California