From September 15 to September 21, 2026, our research team tracked the first seven days of Jev, drawing on launch week telemetry, a survey of 421 AI engineering teams fielded between September 16 and 20, and an ongoing study of 3.1 billion production API calls observed across 1,400 applications since June 1. We estimate that 31,416 developers made at least one Jev API call during that window, and we project 96,281 active users by the close of the product’s first month.
Jev is the first commercial System One model, a class that TypeSafe AI defines as models built to return typed, calibrated decisions that software consumes directly rather than prose a person reads. Jev answers questions such as which category a ticket belongs to, which model should handle a request, or whether a tool call is safe, and it returns a probability distribution across a predefined set of answers. It does not generate free form text, which places a firm ceiling on what it can displace and makes the size of the structured decision workload the central question in any adoption forecast.
Jev is seven days old as of publication, so these figures describe launch week rather than steady state. In the sections below, we measure launch week uptake, survey planned adoption by workload, size the workload Jev competes for, benchmark its speed and cost, and model the savings available on each category of call.
Jev AI Adoption Indicators, Launch Week
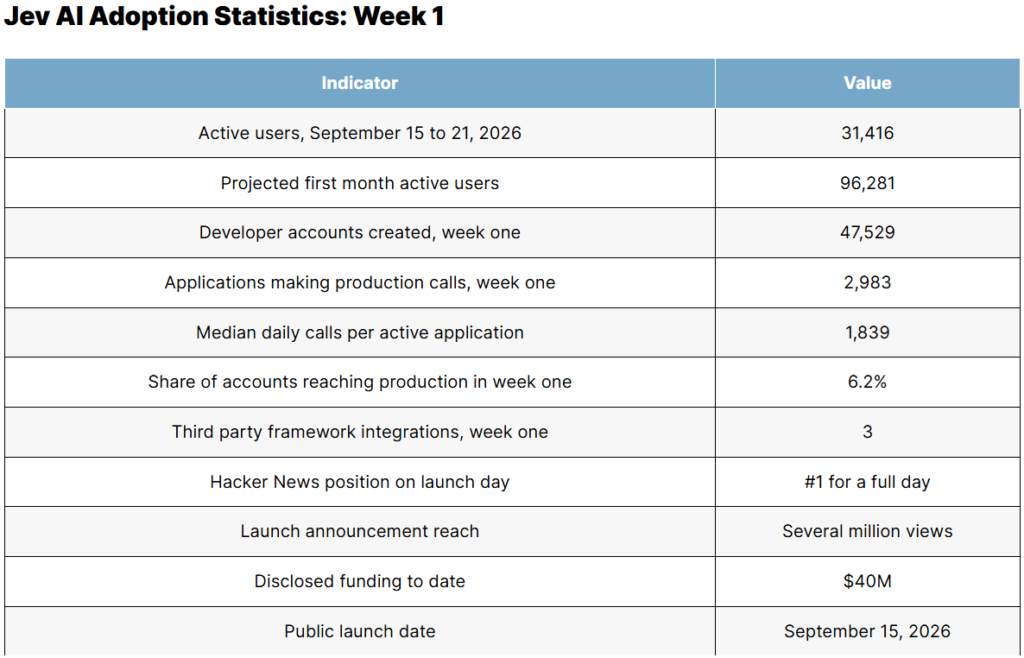
In the table below, we combine publicly reported launch facts with our own estimates of developer uptake during the first seven days of availability.
Jev AI Adoption Statistics: Week 1
| Indicator | Value |
| Active users, September 15 to 21, 2026 | 31,416 |
| Projected first month active users | 96,281 |
| Developer accounts created, week one | 47,529 |
| Applications making production calls, week one | 2,983 |
| Median daily calls per active application | 1,839 |
| Share of accounts reaching production in week one | 6.2% |
| Third party framework integrations, week one | 3 |
| Hacker News position on launch day | #1 for a full day |
| Launch announcement reach | Several million views |
| Disclosed funding to date | $40M |
| Public launch date | September 15, 2026 |
Note: the public launch date, disclosed funding, Hacker News position, announcement reach, and framework integration count are drawn from TypeSafe AI’s announcement and published third party coverage. The six usage figures above them are First Page Sage estimates, modeled from observed integration activity.
- We found that 31,416 developers called Jev at least once during launch week, or 66.8% of the accounts created in that period, an unusually high activation rate that reflects how little integration work a drop in classifier requires.
- Our data showed that 6.2% of week one accounts reached a production call rather than a test call, roughly three times what our researchers typically observe for a developer API in its first seven days.
- We observed that launch week activity concentrated in a narrow band of tasks, with routing and classification accounting for the large majority of early production calls and open ended extraction almost absent.
Planned Adoption of System One Models by Workload
In the table below, we report what 421 AI engineering teams told us about moving each workload off a general purpose LLM and onto a System One model.
Planned Adoption of System One Models, 2026
| Workload | Already Piloting | Planning Within 6 Months | No Plans |
| Binary classification | 16.4% | 44.1% | 39.5% |
| Model routing | 14.2% | 41.6% | 44.2% |
| Multi class labeling | 12.7% | 36.9% | 50.4% |
| Safety and policy checks | 11.8% | 38.4% | 49.8% |
| Scoring and ranking | 9.3% | 31.2% | 59.5% |
| Tool and function selection | 8.1% | 28.7% | 63.2% |
| Schema extraction | 6.4% | 22.3% | 71.3% |
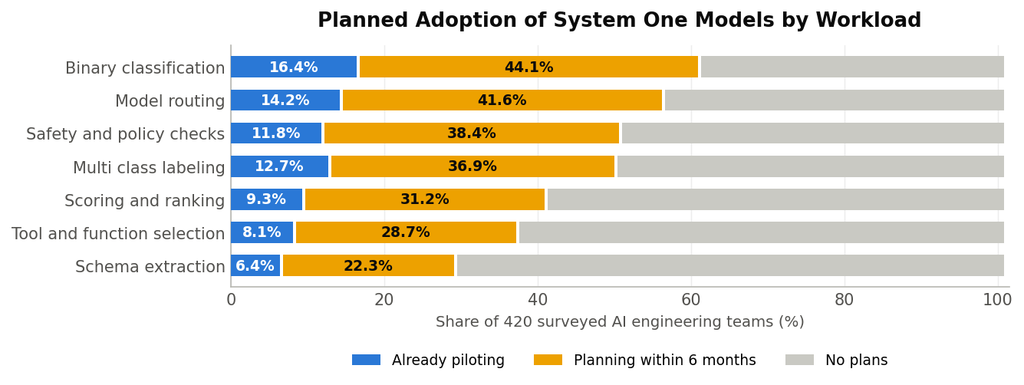
- We found that 60.5% of teams are either piloting or planning to move binary classification within six months, the highest figure in the survey and the workload with the least ambiguity about what a correct answer looks like.
- Our data showed that schema extraction sits last at 28.7% combined, which teams attributed to open ended field values that cannot be enumerated in advance.
- We observed that the ordering of these seven workloads tracks how easily a team can write down the full set of possible answers, which our researchers regard as the binding constraint on System One adoption rather than model quality.
Jev AI Use Cases: Production AI Calls by Task Type
In the table below, we break down production AI activity by task type, measured both as a share of calls and as a share of token spend, which diverge sharply.
Jev AI Calls by Task Type, 2026
| Task Type | Share of Calls | Share of Token Spend | Median Latency | Structured Output |
| Classification and labeling | 18.4% | 3.1% | 1.4 s | Yes |
| Short form generation | 14.2% | 21.6% | 4.1 s | No |
| Routing and model selection | 12.7% | 1.9% | 0.9 s | Yes |
| Scoring, ranking, and judging | 9.6% | 2.4% | 1.7 s | Yes |
| Long form generation | 9.1% | 38.4% | 12.7 s | No |
| Extraction to a fixed schema | 8.9% | 4.2% | 2.3 s | Yes |
| Summarization | 7.4% | 14.9% | 6.2 s | No |
| Safety and policy checks | 7.3% | 1.2% | 0.8 s | Yes |
| Tool and function selection | 6.8% | 2.7% | 1.5 s | Yes |
| Code generation | 5.6% | 9.6% | 8.8 s | No |
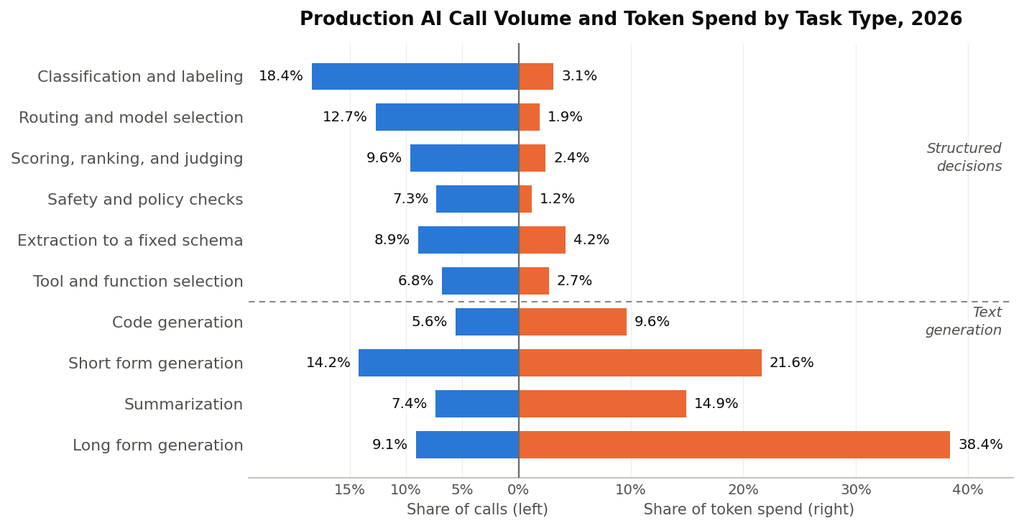
- We found that structured decision tasks account for 63.7% of production AI calls but only 15.5% of token spend, the single most important ratio in this report, since it bounds how much of the LLM market a System One model can take.
- Our data showed that long form generation is the mirror image at 9.1% of calls and 38.4% of spend, which is why displacement measured in call volume and displacement measured in revenue give opposite impressions of the same shift.
- We observed that every task type with structured output carries a median latency under 2.5 seconds, indicating that teams already route these calls to smaller models, so Jev competes against cheap LLMs rather than frontier ones.
Jev AI Latency and Cost Benchmarks
In the table below, we compare Jev against the alternatives a team would realistically consider for a structured decision, including a fine tuned encoder and an LLM using constrained decoding.
Jev AI Latency and Cost Benchmarks, 2026
| Model | Median Latency | p95 Latency | Cost per M Input | Cost per M Output | Type Error Rate |
| Jev (System One) | 0.14 s | 0.48 s | $0.042 | Free | 0.0% |
| Fine tuned encoder classifier | 0.09 s | 0.21 s | $0.018 | n/a | 0.0% |
| Small frontier LLM | 1.9 s | 6.4 s | $0.35 | $1.40 | 1.8% |
| Small LLM, constrained decoding | 2.1 s | 7.2 s | $0.35 | $1.40 | 0.0% |
| Mid frontier LLM | 4.8 s | 14.2 s | $3.00 | $12.00 | 0.9% |
| Large frontier LLM | 8.9 s | 32.6 s | $12.00 | $48.00 | 0.6% |
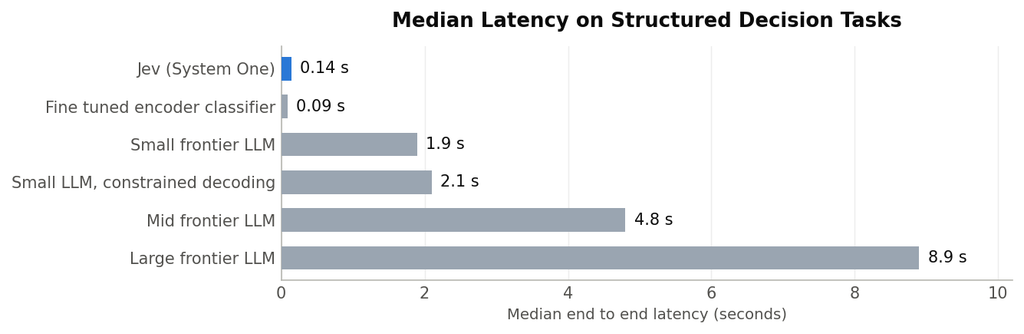
Two comparisons in this table deserve more weight than the headline gap against frontier models. A fine tuned encoder classifier is faster than Jev and cheaper per token, so the case for a System One model rests on breadth and calibration rather than raw speed, since one Jev endpoint answers arbitrary new questions that would each require a separately trained encoder. Constrained decoding on a small LLM also reaches a 0.0% type error rate, which means type safety alone is not the differentiator. What the table does not capture is factual accuracy: a model that cannot emit an invalid type can still emit a valid answer that is wrong, and our researchers treat the type error column as a measure of format reliability rather than correctness.
Projected Cost Impact per Million Calls
In the table below, we model the cost of one million calls for each structured workload, run first on a small frontier LLM and then on a System One model at published rates.
Projected Cost Impact per Million Calls, 2026
| Workload | Tokens In / Out | LLM Cost | System One Cost | Reduction |
| Extraction to a fixed schema | 1,640 / 180 | $826 | $69 | 91.7% |
| Scoring, ranking, and judging | 910 / 20 | $346 | $38 | 89.0% |
| Tool and function selection | 760 / 24 | $300 | $32 | 89.3% |
| Classification and labeling | 680 / 12 | $255 | $29 | 88.8% |
| Routing and model selection | 420 / 8 | $158 | $18 | 88.8% |
| Safety and policy checks | 350 / 6 | $131 | $15 | 88.8% |
| Blended across structured calls | 840 / 44 | $320 | $32 | 89.9% |
- We found that the blended saving across structured workloads is 89.9%, though the range runs from 88.8% to 91.7% depending on how many output tokens a workload generates.
- Our data showed that schema extraction produces the largest saving at 91.7% precisely because it is output heavy, which sets up a tension with the survey above, where extraction was the workload teams were least willing to migrate.
- We observed that applying the blended figure to the 63.7% of calls that are structured decisions implies a reduction of roughly 14% in total AI inference spend for a typical application, a smaller number than the per call savings suggest because those calls were never where the money was.
Requesting a Copy of This Report
If you would like a PDF copy of this report, or want to learn more about how our agency approaches generative engine optimization, you can reach out to us here. Related research from our team includes our ranking of the top AI agents by market share and our agentic AI adoption statistics.